
Why This Matters, by Stakeholder
- Users and dapp developers. Lower average handover latency means less idle time between leaders, and thus more slots per unit of wall-clock time. This may affect transaction senders, who should not assume that consecutive leaders are geographically independent.
- Validators. Validators in sparse locations benefit most, as they are much more likely to have a nearby predecessor than today. The number of leader windows a validator gets in an epoch is unchanged, only their respective order changes.
- Core contributors. The leader schedule computation becomes more complex and depends on reported locations.
TL;DR
- Geo-aware leader schedule is promising to improve handoff latency, reducing pressure for stake concentration in macroregions
- This analysis shows that the
STAKE_FLOORparameter (denoted with here) should stay around 10%- Higher values make the fake-location attack more expensive, but above 10%, Asia (about 10.4% of stake today) loses local bins
- For the
RUN_LENGTHparameter (denoted with here) should not go above 7- It depends on which risk we want to minimize, and ranges between 3 and 7
- When coalitions are considered, if we fix , our simulation framework suggests a limited absolute increase in MEV-opportunity rising from consecutive leader windows
Relevant Charts
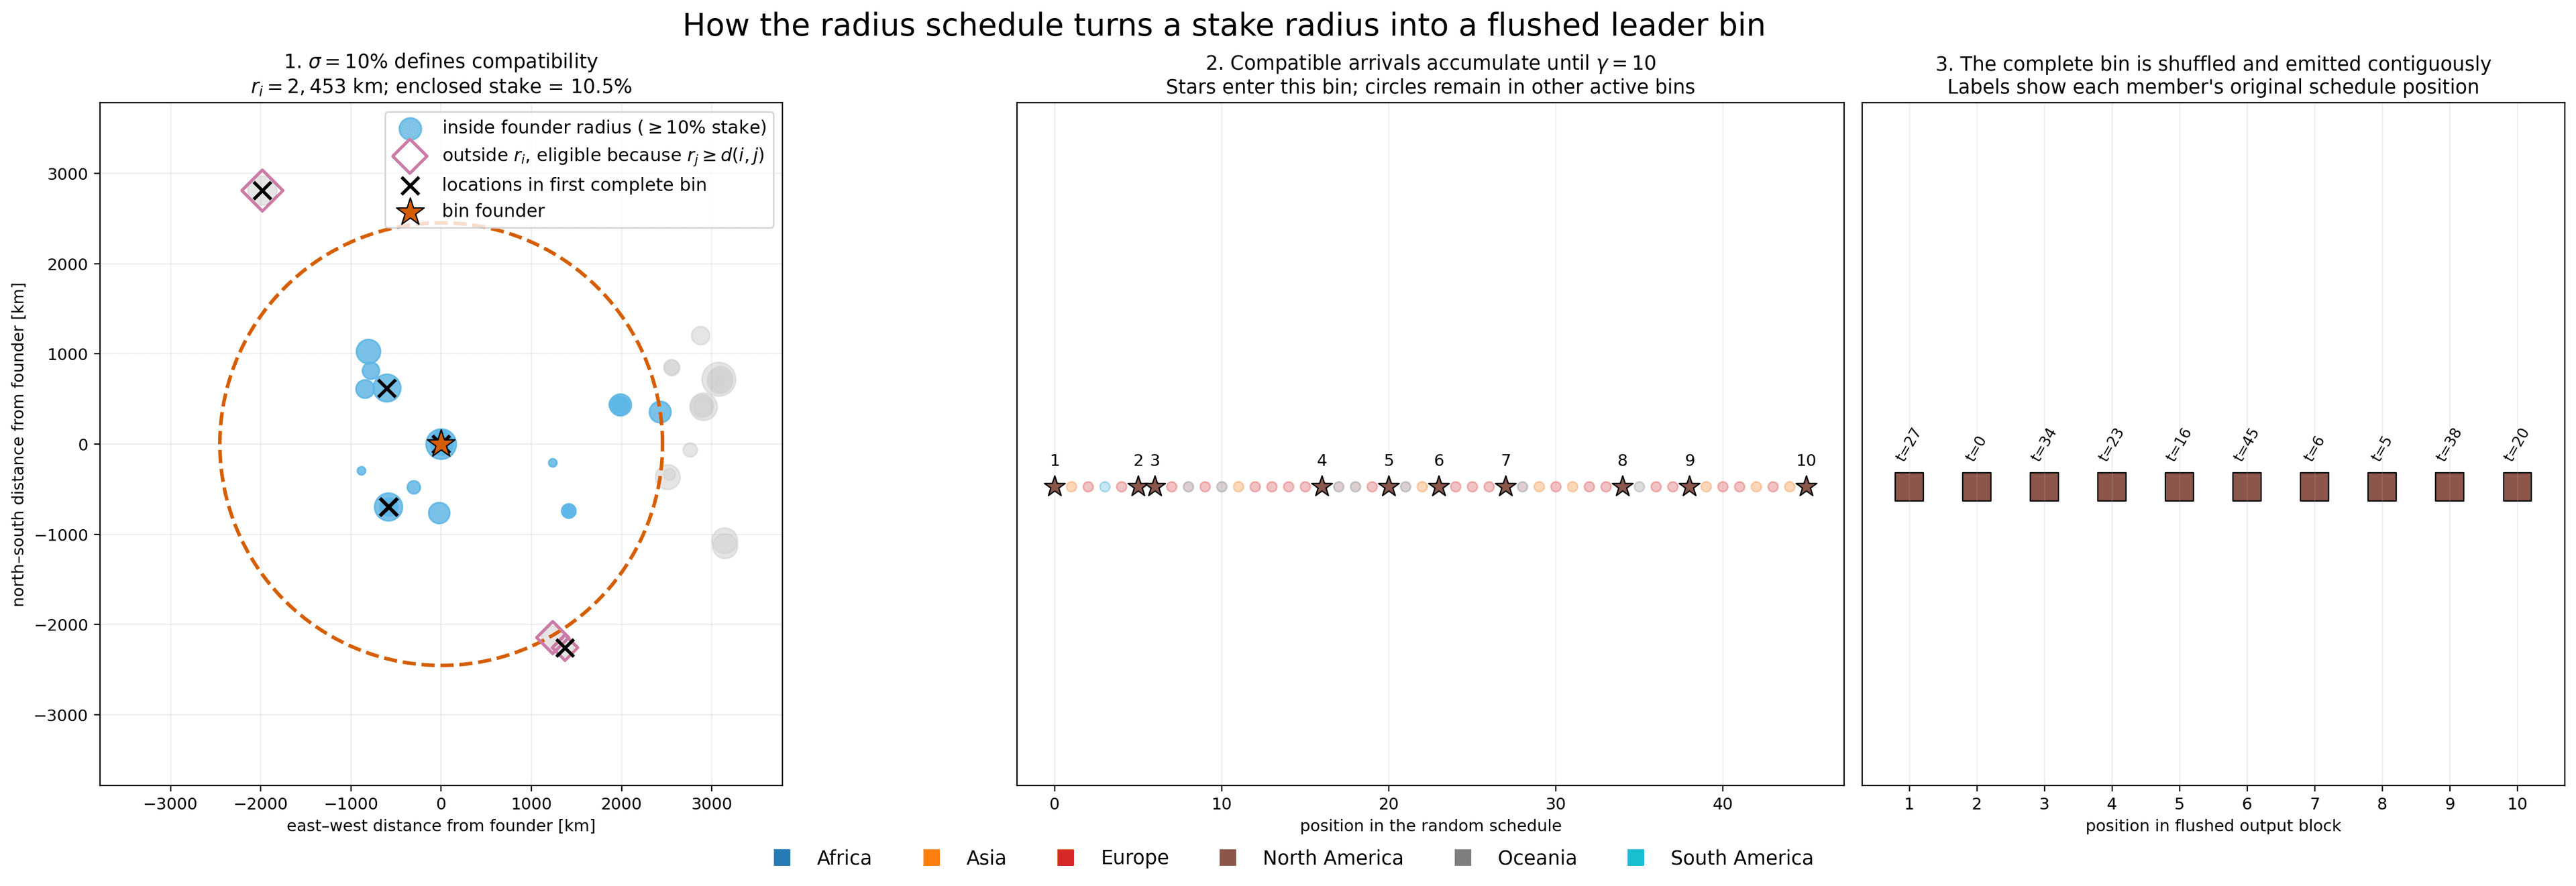
Left: the founder radius at and the locations compatible with it. Centre: compatible leaders accumulate in the bin until . Right: the full bin is shuffled and emitted contiguously.
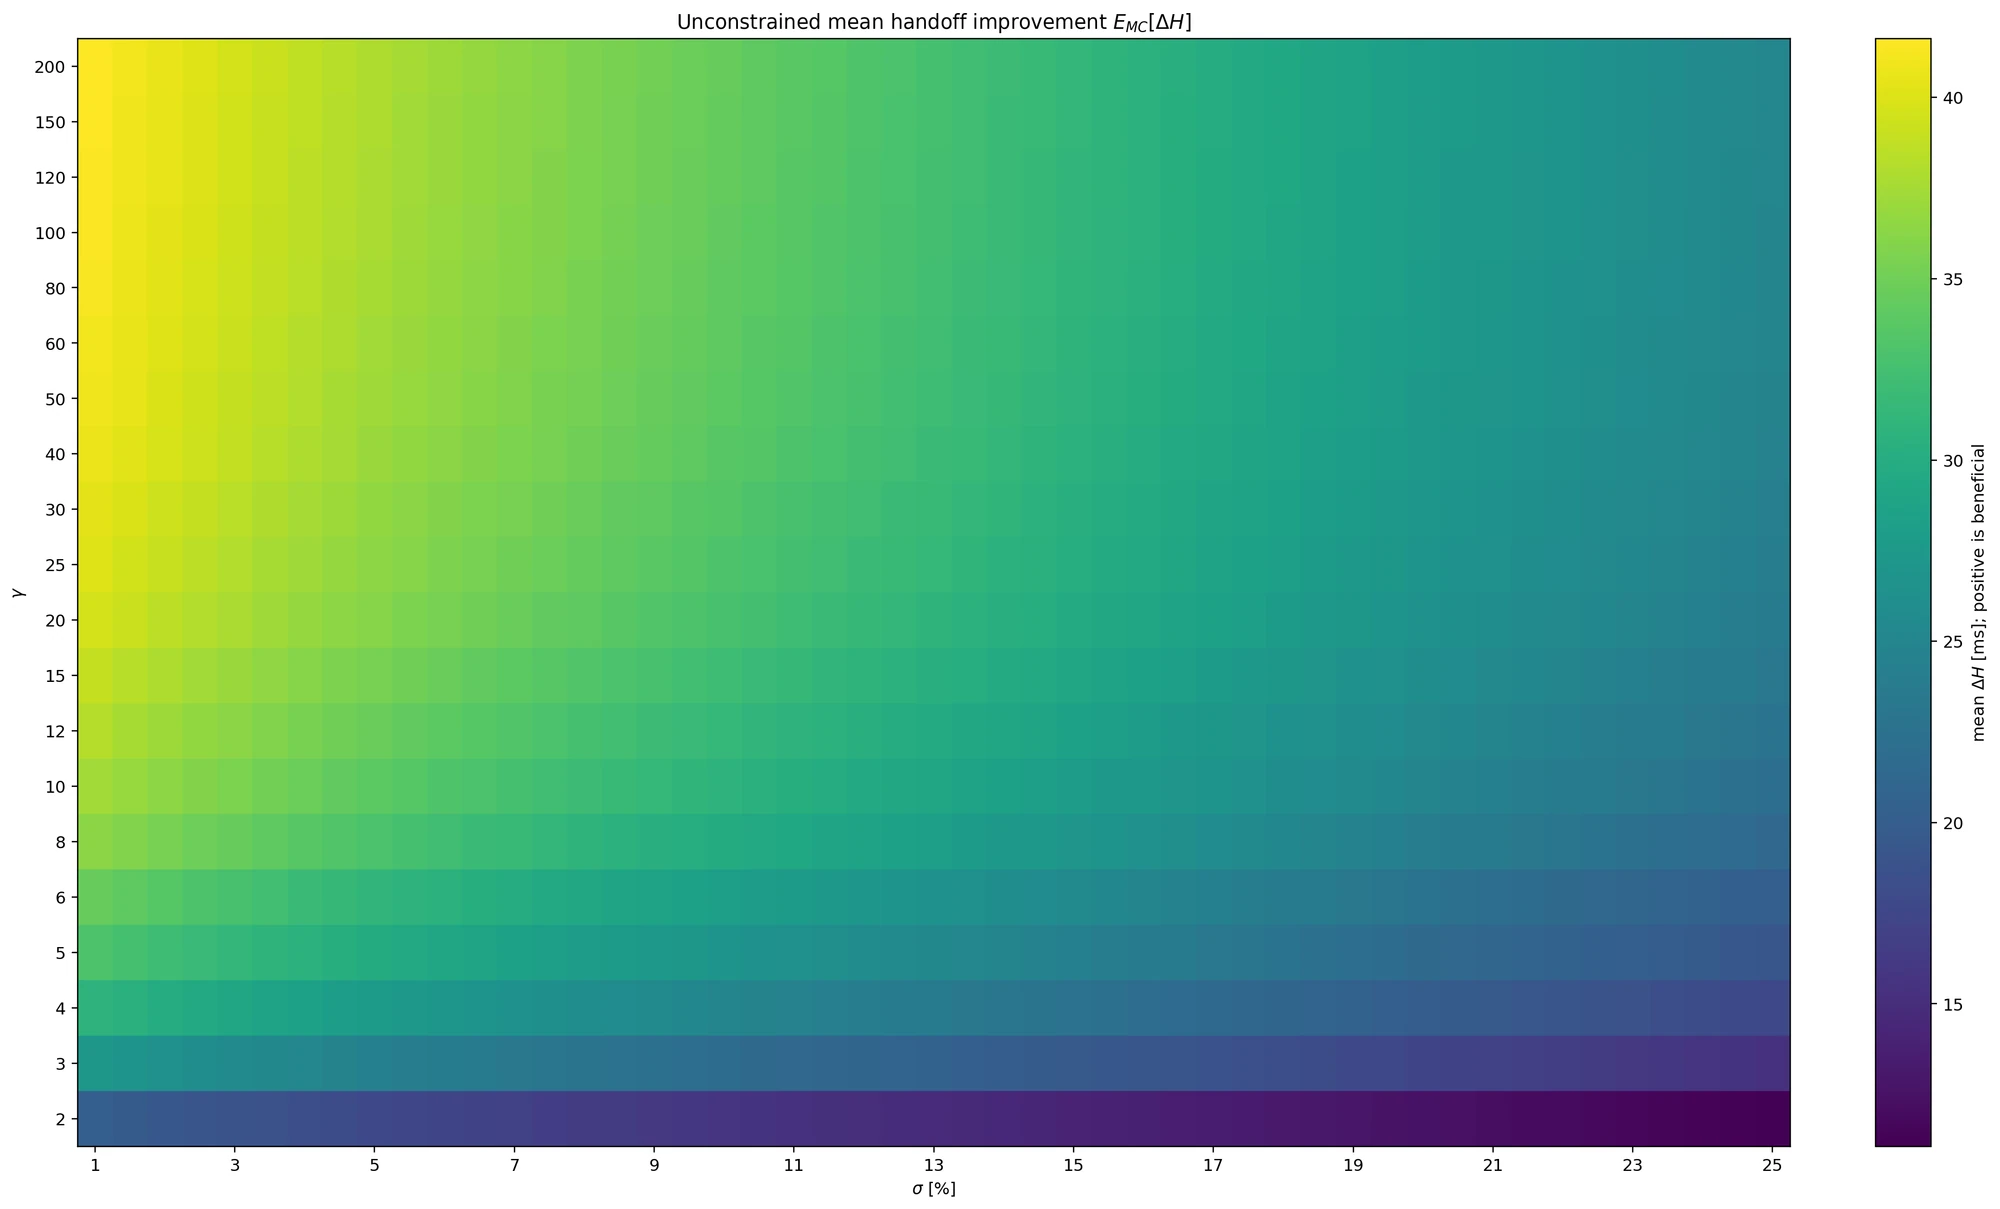
Mean handoff gain across all synthetic networks in the simulations, for every parameter selection.
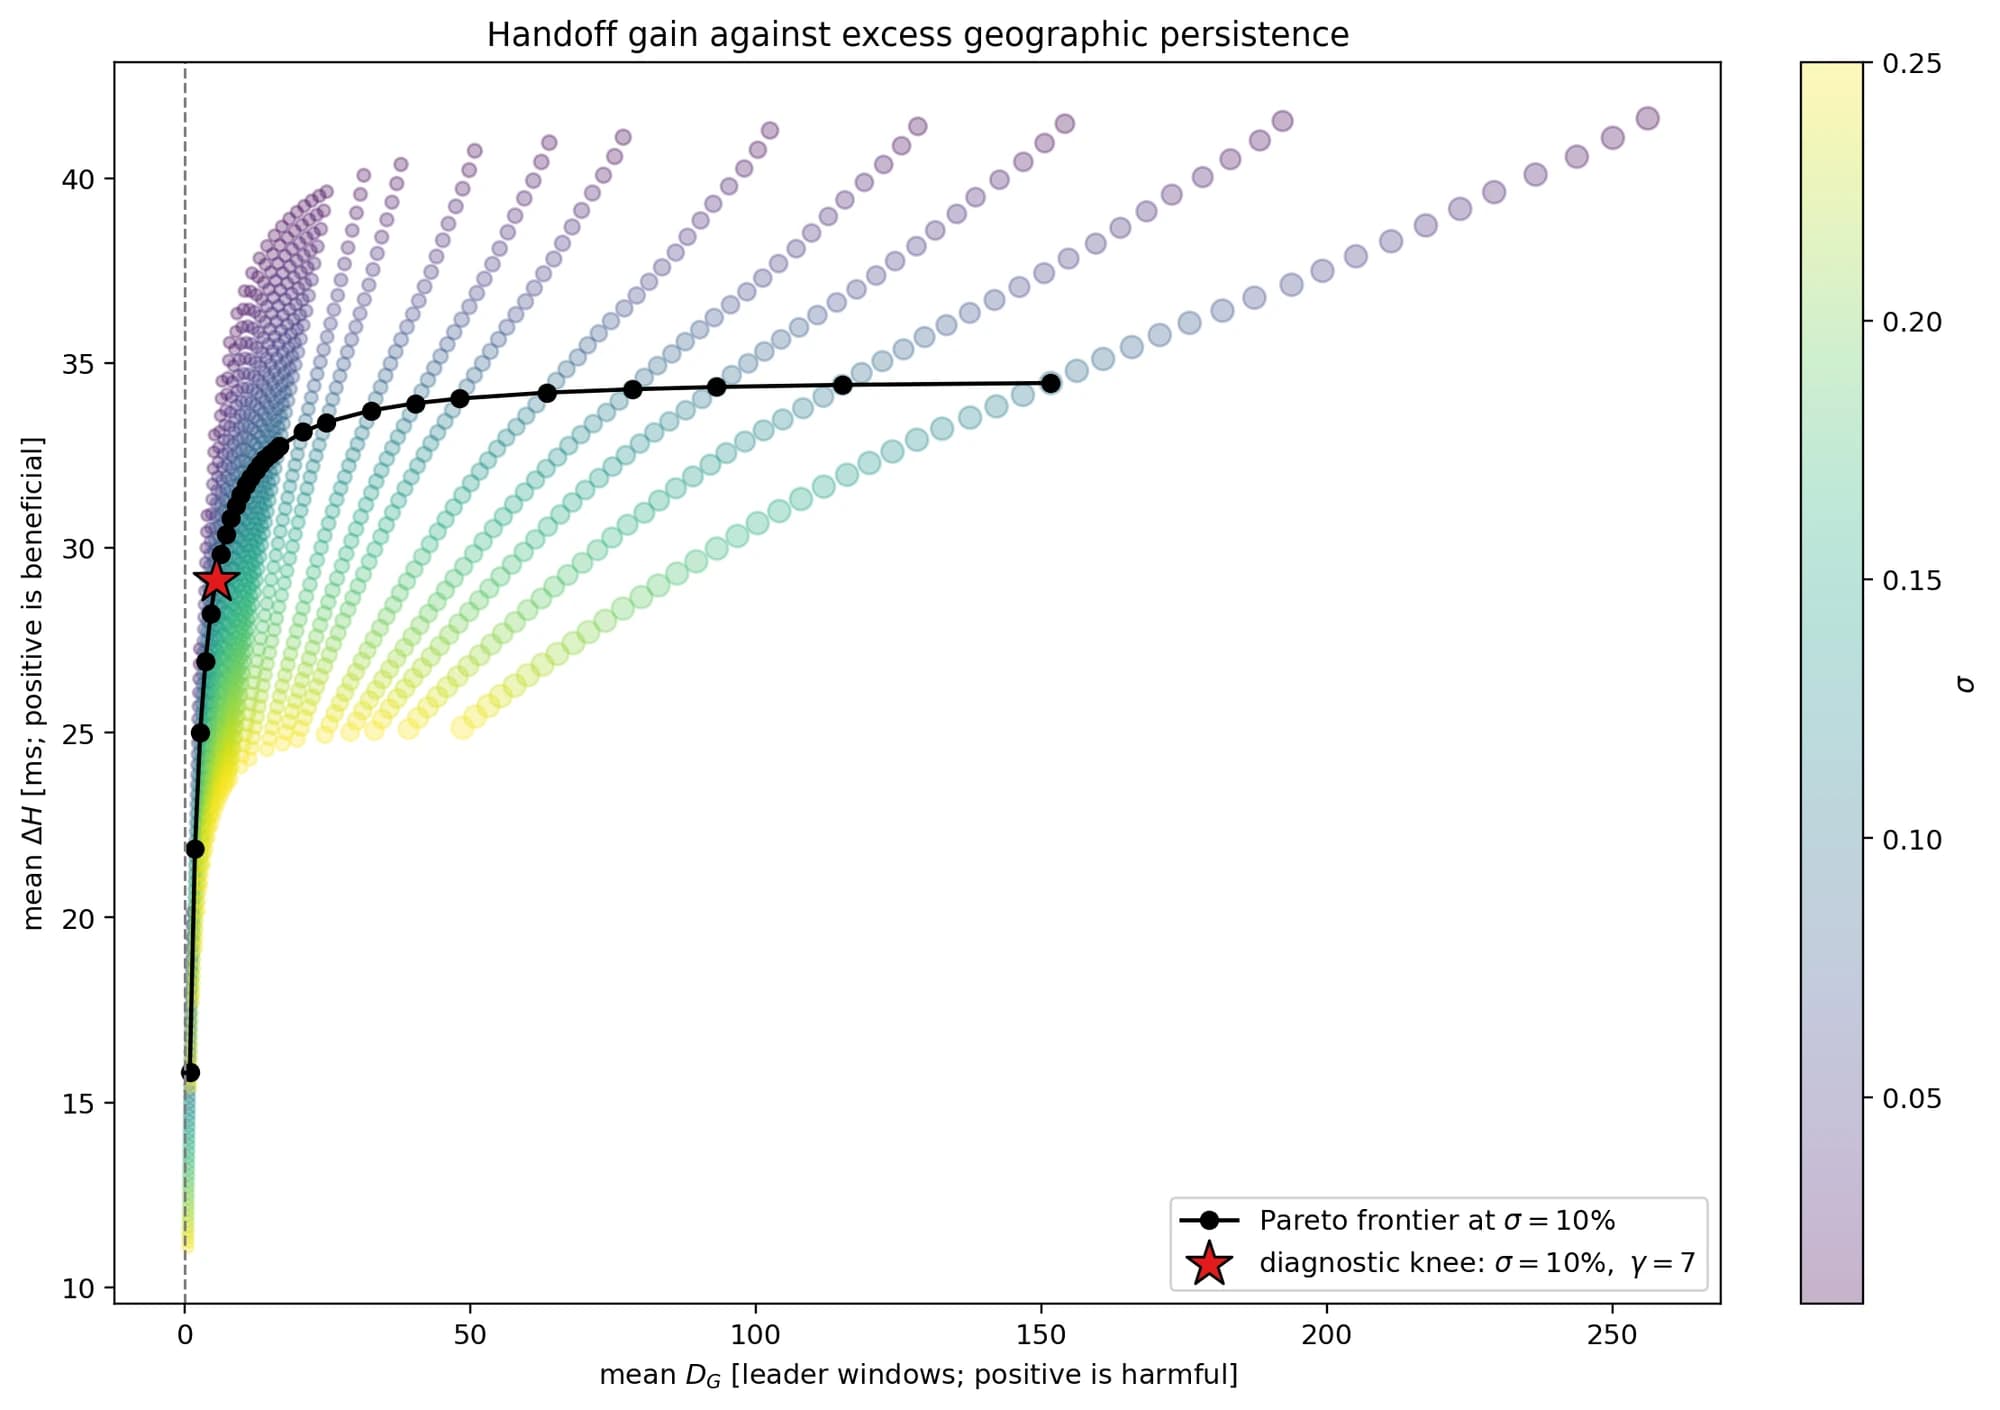
Mean handoff gain against mean excess geographic persistence , across synthetic networks. Every simulated is shown, colored by and sized by . The black line is the Pareto frontier at ; the star marks its knee, computed for .
Introduction
Solana’s leader schedule is what decides which validators are entitled to produce a slot.
The current schedule assigns windows of 4 consecutive slots to each validator every epoch. The selection criteria are based on validators’ stake.
Despite being costly to attack, a random schedule carries a well-known issue: it ignores where validators are located. Two consecutive leaders can sit in the same data center or on opposite sides of the planet. In the second case, the handoff (passage from one leader to the other) costs tens of milliseconds of pure propagation delay.
SIMD-0675 proposes a geo-aware leader schedule. In order to preserve some of the good properties of the random scheduler, the core extraction mechanism is not replaced. It takes the same random schedule as input and only changes the order. Every validator keeps exactly the same number of leader windows it would have had.
The reordering depends on two parameters (see Fig. 1):
- (
STAKE_FLOOR): For every location we compute a radius : the smallest distance that contains at least a fraction of the total stake. Dense areas get small radii, isolated validators get large ones. Two leaders are compatible when their distance is within the larger of their two radii - (
RUN_LENGTH): We go through the random schedule in order. Each leader joins a compatible open bin, chosen at random, or opens a new one. When a bin reaches leaders, it is shuffled and written to the final schedule as one contiguous block.
Fig. 1: Left: the founder radius at and the locations compatible with it. Centre: compatible leaders accumulate in the bin until . Right: the full bin is shuffled and emitted contiguously.
The idea is simple: consecutive leaders become geographically close, so the handoff becomes shorter. But this comes at a price: the final ordering is moving away from the random leader schedule.
The goal of this analysis is to quantify the trade-off between latency gain and attack surface expansion, eventually providing a guide for parameter selection. Precisely, we try to answer the question: How much latency do we gain for a given choice of , and how far does the schedule move from random to get it?
The analysis is structured to first present all the metrics employed. In the second part we use the observed behaviour to provide sensible values for these parameters.
Relevant SIMDs are
The Parameter Selection Tradeoffs
Network state is constantly changing. Stake can redistribute, nodes can move around, new coalitions can form. Thus, we can’t study how parameters affect today’s network, but we need to add perturbations.
In this analysis, we keep the 124 locations where Solana validators run today, grouped in six macroregions, and generate 6,250 synthetic networks on top of them by redistributing nodes and stake with different levels of concentration (see Appendix A).
Due to the absence of evidence of other sites ready to host Solana nodes today, we add no new locations to the simulation pipeline. The geography therefore stays as unbalanced as it is now.
All conclusions are conditional on this geography. If new locations become available in the smaller regions, or stake moves significantly across regions, they should be revisited.
Handoff Gain
In order to measure the latency improvement, we employ the handoff for a schedule defined as the average latency between consecutive leaders,
where is the total number of leader windows in the simulations (108,000 here), is the leader of window , and is the estimated latency between leader and leader . We estimate it from distance only: , i.e. signals travel in fiber at about two thirds of the speed of light along a path 50% longer than the great-circle distance.
The gain over random is
so positive values mean the geo-aware schedule is faster than random.
Fig. 2: Mean handoff gain across all synthetic networks in the simulations, for every parameter selection.
Figure 2 shows two clear trends. The gain grows with and shrinks with . At , it goes from 15.8 ms at to 33.9 ms at . At fixed , moving from to costs roughly a third of the gain.
This behaviour is expected by the nature of the parameters:
- A smaller means smaller radii, so leaders in the same bin are closer to each other
- In a block of leaders, handoffs are between compatible leaders and only the last one jumps to the next bin. The share of long jumps is then roughly .
It is interesting to observe that, the second point explains why the gain saturates. Going from to only removes a small share of the long jumps, and that share keeps shrinking. At , already gives 65% of the gain observed at , gives 79%, and gives 91%. Beyond , each additional leader per bin buys very little latency.
Geographic Persistence
The purpose of a geo-aware schedule is to group leader from the same area. Inevitably, this means that the network stays longer in one macroregion. If that region has a problem, such as an outage at a large provider, local censorship or a regional network partition, the network is exposed to it for longer than under random.
This is clearly lowering the resilience of the network. Thus, we need to measure the “loss” we get when we change the parameters.
We measure the probability that consecutive leader windows all fall in the same macroregion,
where is the macroregion of the leader . We measure excess cumulative geographic persistence relative to random as
For each , the starting position is uniform over the valid positions. sums excess homogeneus-block probabilities across lengths. It measures cumulative geographical persistence.
It is worth mentioning that, also provides a proxy for additional time spent consecutively in the same macroregion. For , and for suffciently larger , the residual same-region duration can be expressed as
where represents the duration of one leader window. Consequently, is expressed in leader windows, and multiplying it by 0.8s gives a time-scaled persistence measure. Throughout the text and figures, references to additional windows or seconds of geographic persistence use this approximate interpretation.
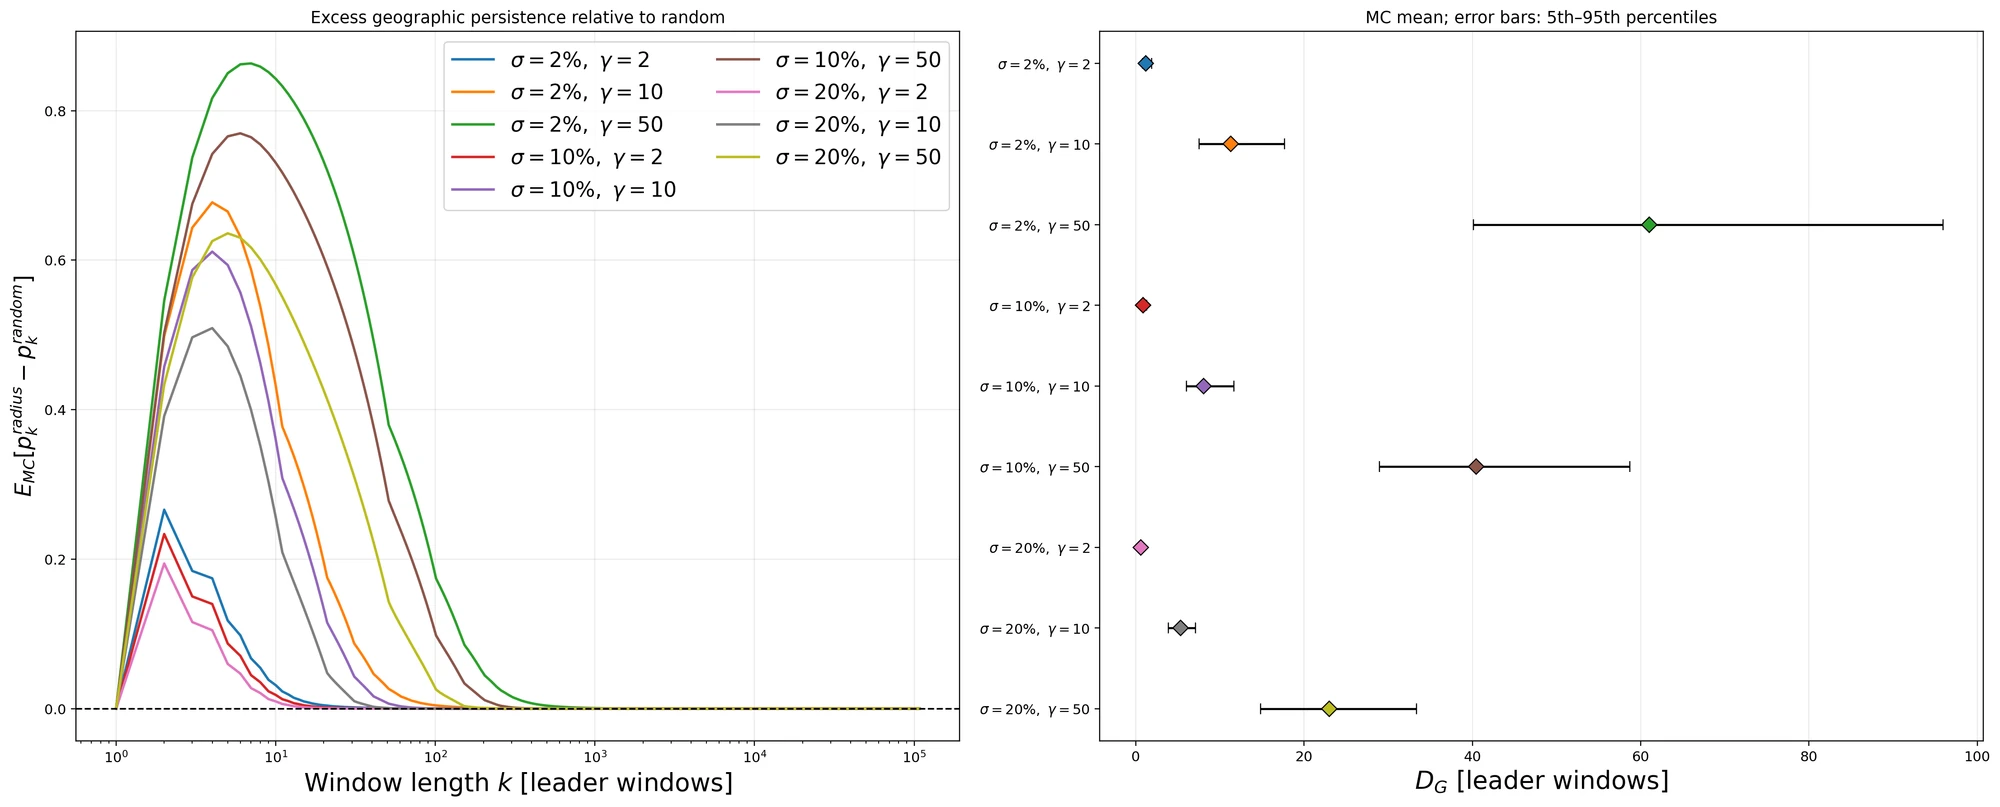
Fig. 3: Left: mean excess persistence as a function of the window length (in leader windows). Right: , MC mean with 5th–95th percentiles across synthetic networks.
The excess peaks at short horizons, a few windows, and then decays. Two things control it.
- It is clear that is the dominant factor. Larger bins mean longer same-region blocks, so both the peak and the tail grow. With the excess is gone after about 20 windows; with it lasts for a few hundred
- Moving reduces the excess of geographic persistence. This is because a larger gives larger radii, so bins mix more locations and more regions. At , goes from about 61 windows at to about 23 at , and the spread across networks shrinks as well.
This is the first trade-off. For the handoff, smaller and larger are better. For persistence, both are worse. Larger bins buy latency with longer stays in one region, and smaller radii make those stays more likely.
Regional Occupancy
Persistence counts uninterrupted runs. A single leader from another region breaks a run, even if the network then goes back to the same region. To capture how concentrated the schedule is over a whole interval, we look at the share of the most represented macroregion in a window of consecutive leader windows
Under random, every interval contains each region roughly in proportion to its stake. A curve shifted to the right of random means that intervals are more often dominated by one region.
We use four horizons: 38, 375, 1,125 and 2,250 leader windows. With 200 ms slots these are about 30 seconds, 5 minutes, 15 minutes and 30 minutes.
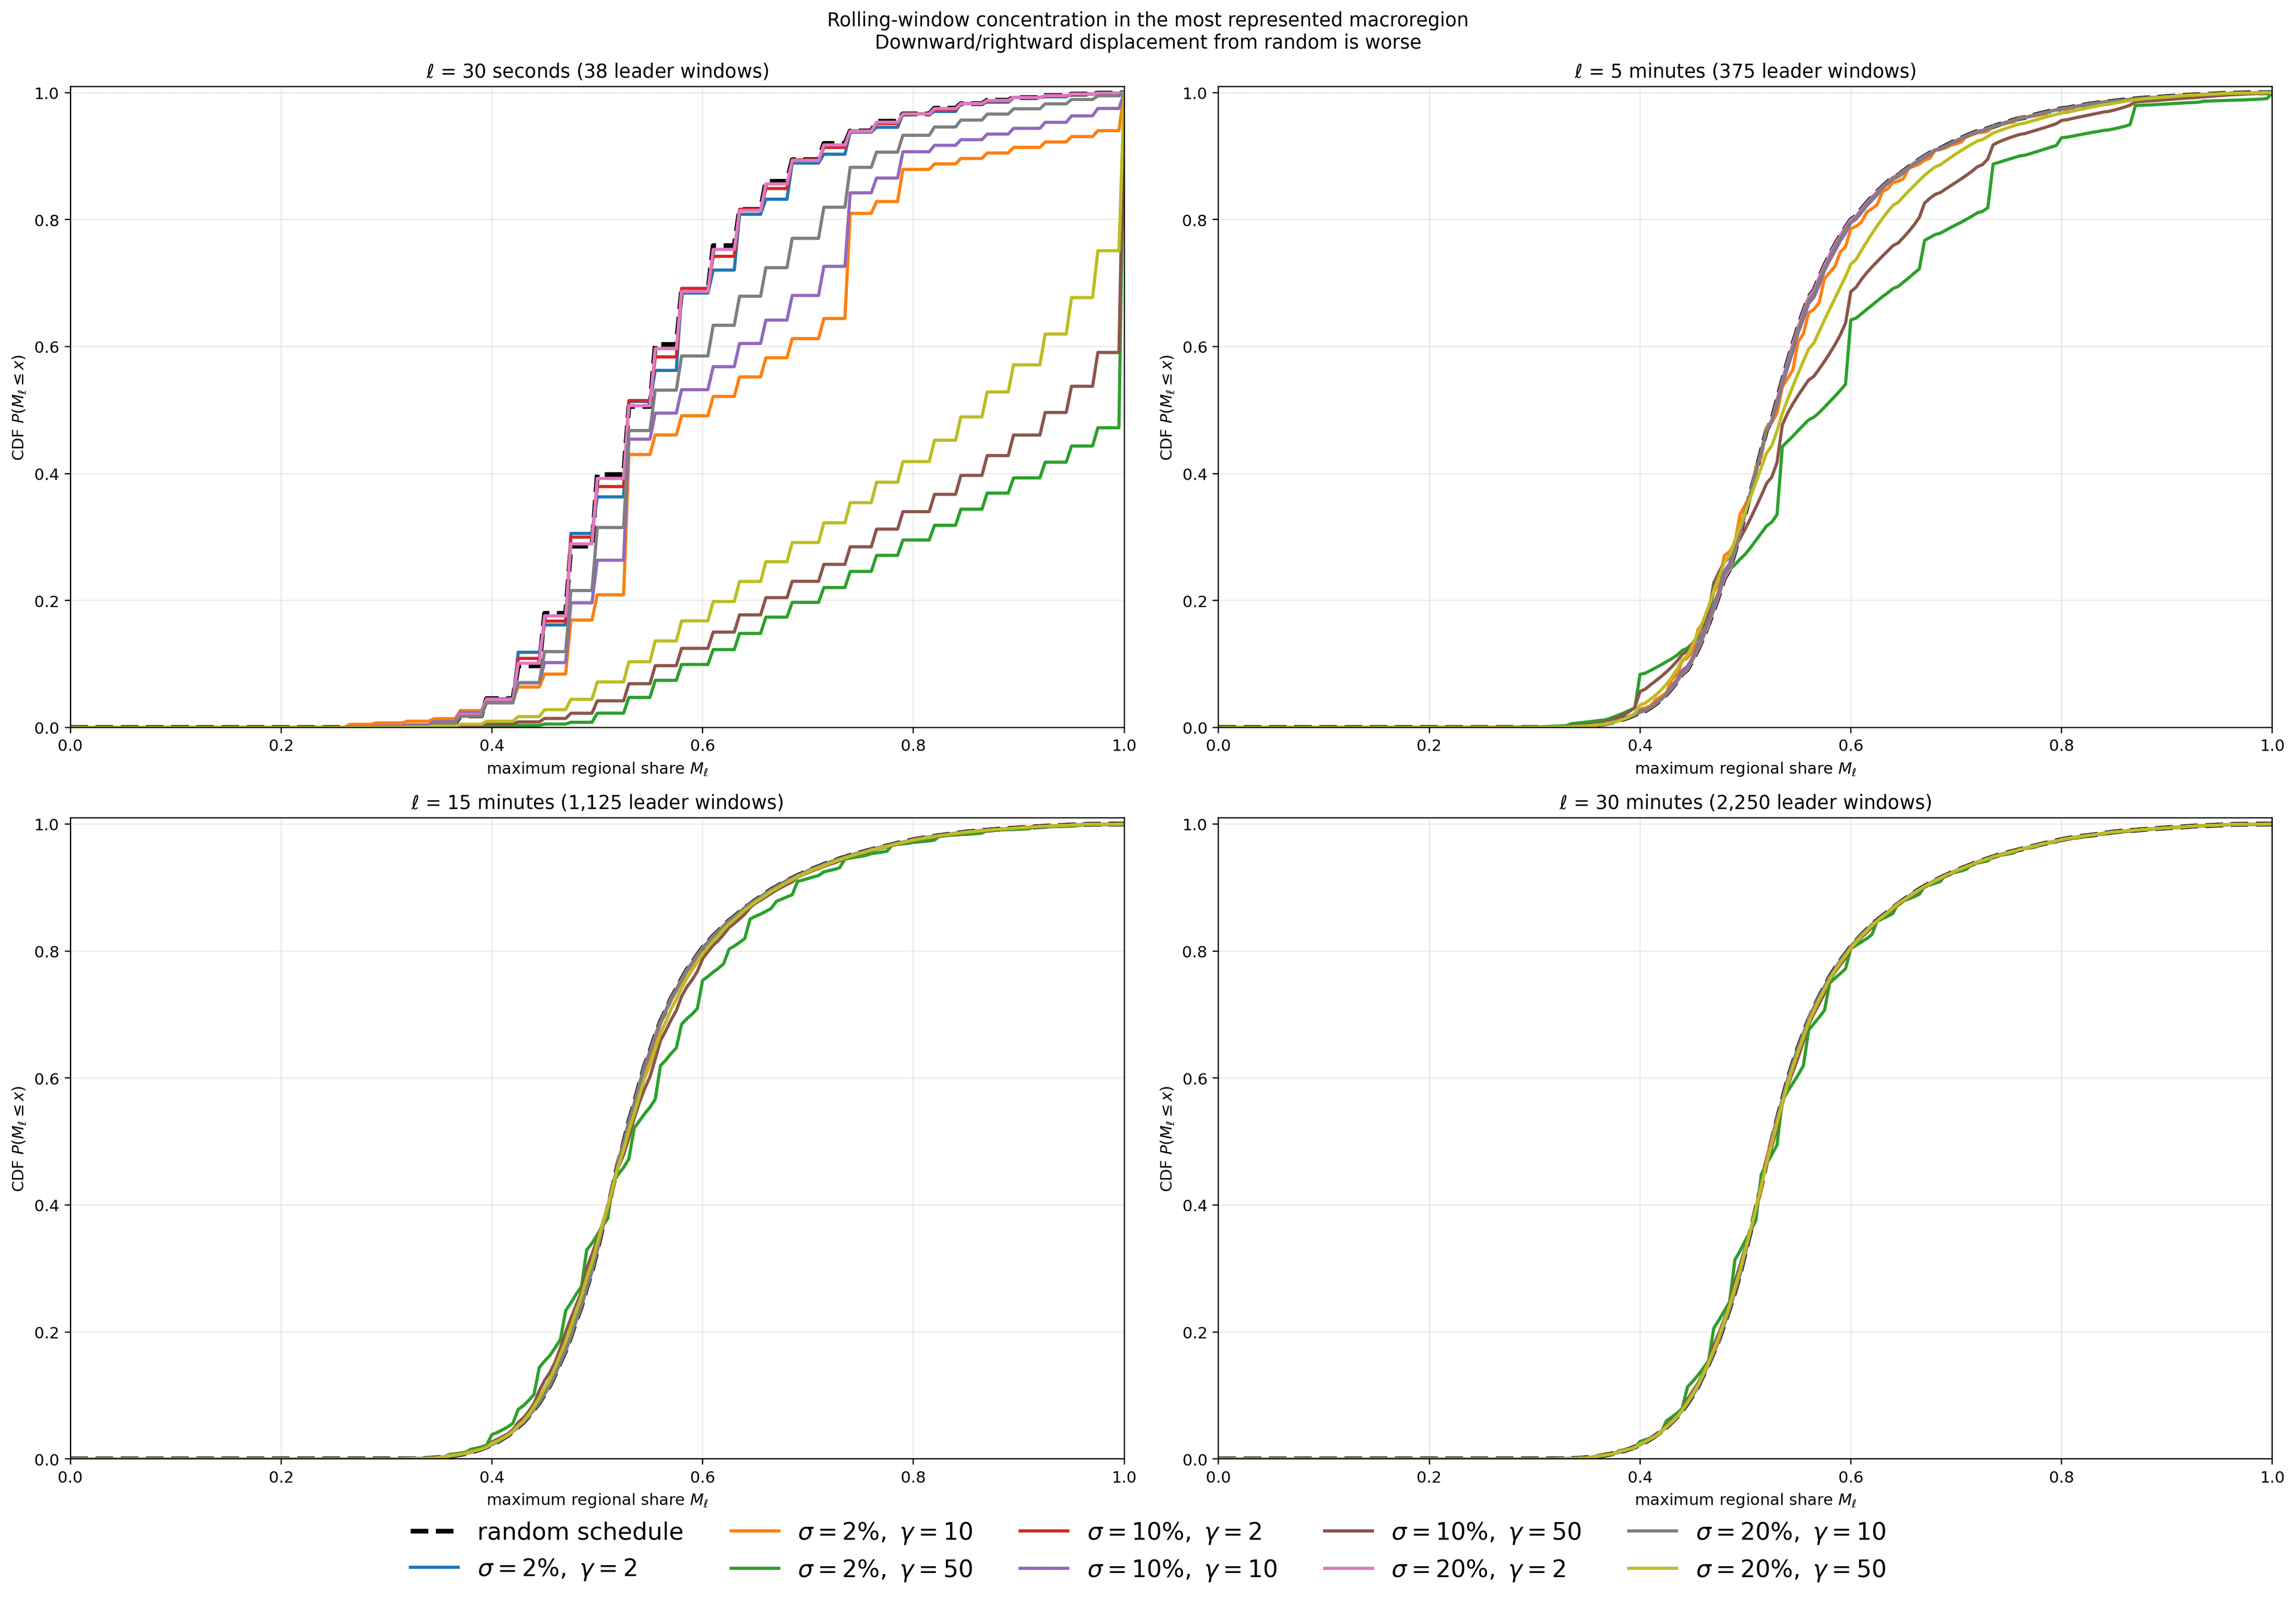
Fig. 4: CDF of the largest regional share over rolling intervals of leader windows, for random (dashed) and selected .
The main message of Fig. 4 is that concentration is a short-horizon effect.
- At 38 windows (~30 s) the differences are large. With the schedule is indistinguishable from random. With the curves move clearly to the right. With a large fraction of intervals is dominated by a single region, for every . At , the mean excess of over random is 0.5 percentage points at , 5.9 at and 29.5 at .
- At 2,250 windows (~30 min) all configurations mostly overlap with random.
This follows from how the schedule is built. The leader multiset is preserved and bins are flushed roughly in the order they fill. A leader is moved only by the time it takes its bin to fill. Over long horizons the regional composition is therefore the same as random; what changes is how regions are arranged inside the interval. Instead of being mixed, they alternate in blocks.
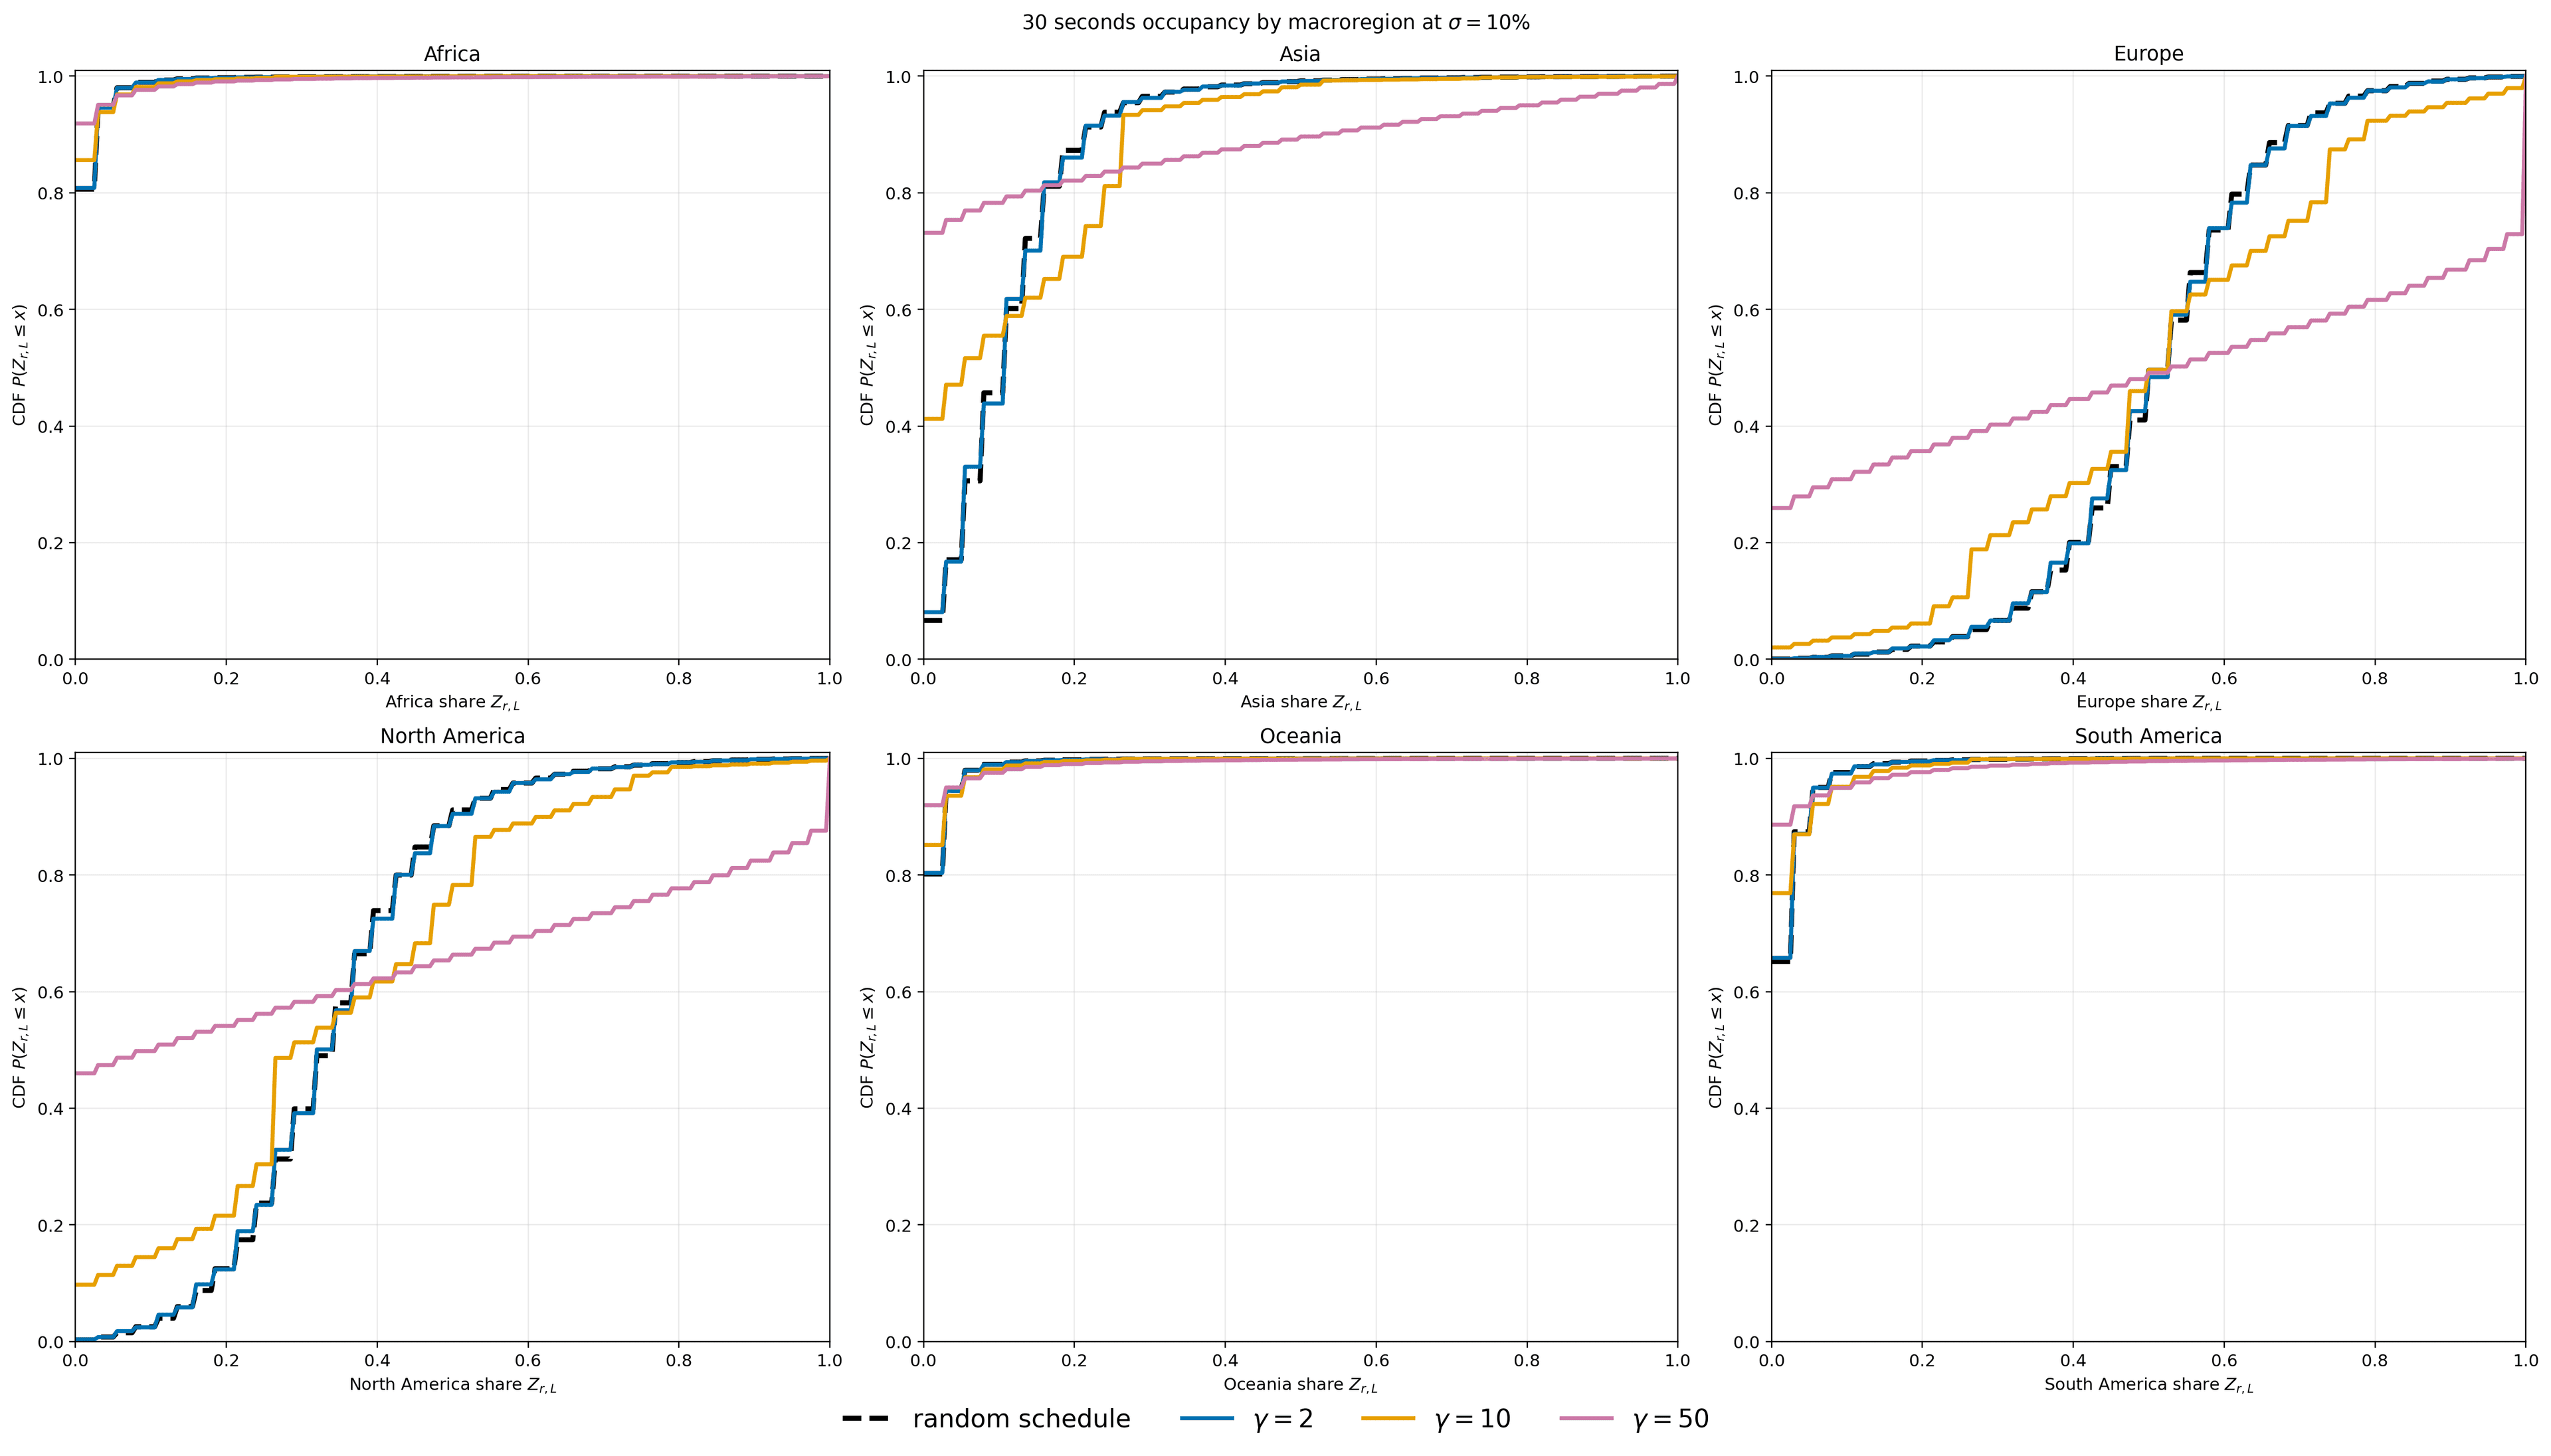
Fig. 5: Regional share over 38 leader windows at , by macroregion.
Figure 5 shows who is affected over short horizons. In Europe and North America, larger makes intervals more extreme: with about a quarter of the 38-window intervals contain no European leader, and roughly the same share contains only European leaders. Asia changes the most in relative terms. Under random, only about 7% of these intervals have no Asian leader; this rises to about 40% at and above 70% at . Africa, Oceania and South America barely move. Their leaders mostly end up in bins founded in other regions (see the spillover section), so they are spread out rather than grouped.
The trade-off is the same as for persistence, but sharper. Short-horizon concentration grows quickly with , while most of the latency gain is already reached at small .
Cross-Region Spillover
The radius is defined by stake, not by geography. If a macroregion holds less than a fraction of the total stake, the radius of its locations has to reach outside the region to collect enough stake. Its bins then mix local and foreign leaders.
For bins founded in macroregion , we measure the share of slots that belong to leaders from other regions,
The founder is always local, so cannot exceed .
Spillover is not a risk with respect to random: a random block mixes regions even more. It tells us instead where the geo-aware schedule actually works. A region with high spillover gets little of the latency gain, and its leaders are spread inside other regions' bins.
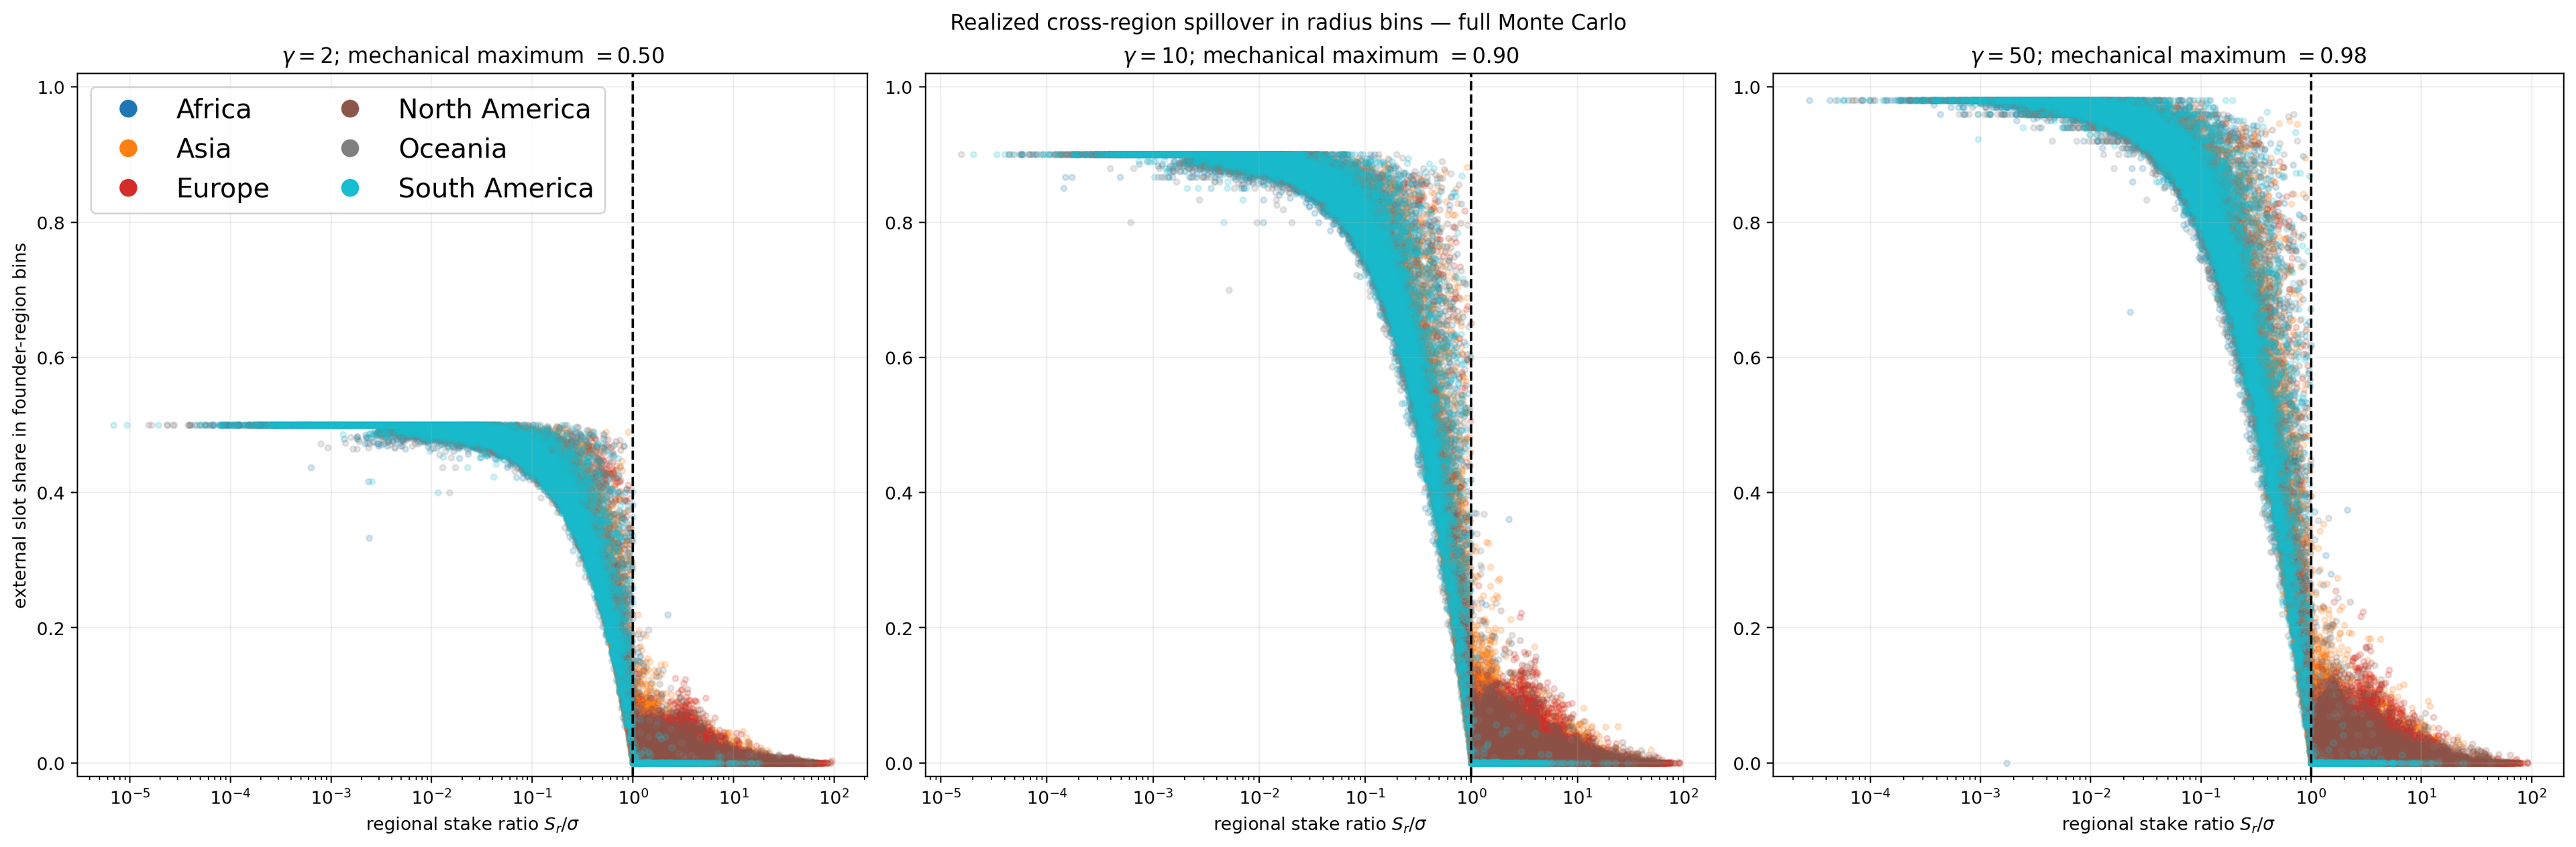
Fig. 6: External slot share in bins founded in each macroregion, against the ratio between regional stake and . Each point is one region in one synthetic network. Dashed line: .
Figure 6 shows that one quantity explains spillover: the ratio . All regions collapse onto the same curve.
- When , bins are almost self-contained. Spillover stays mostly below 10% and decreases as the ratio grows.
- When , spillover rises steeply and quickly reaches its mechanical maximum. Bins founded in the region are filled almost entirely by foreign leaders.
The transition is sharp and sits at . This is the reason for an upper bound on : any region with less stake than is effectively excluded from local bins.
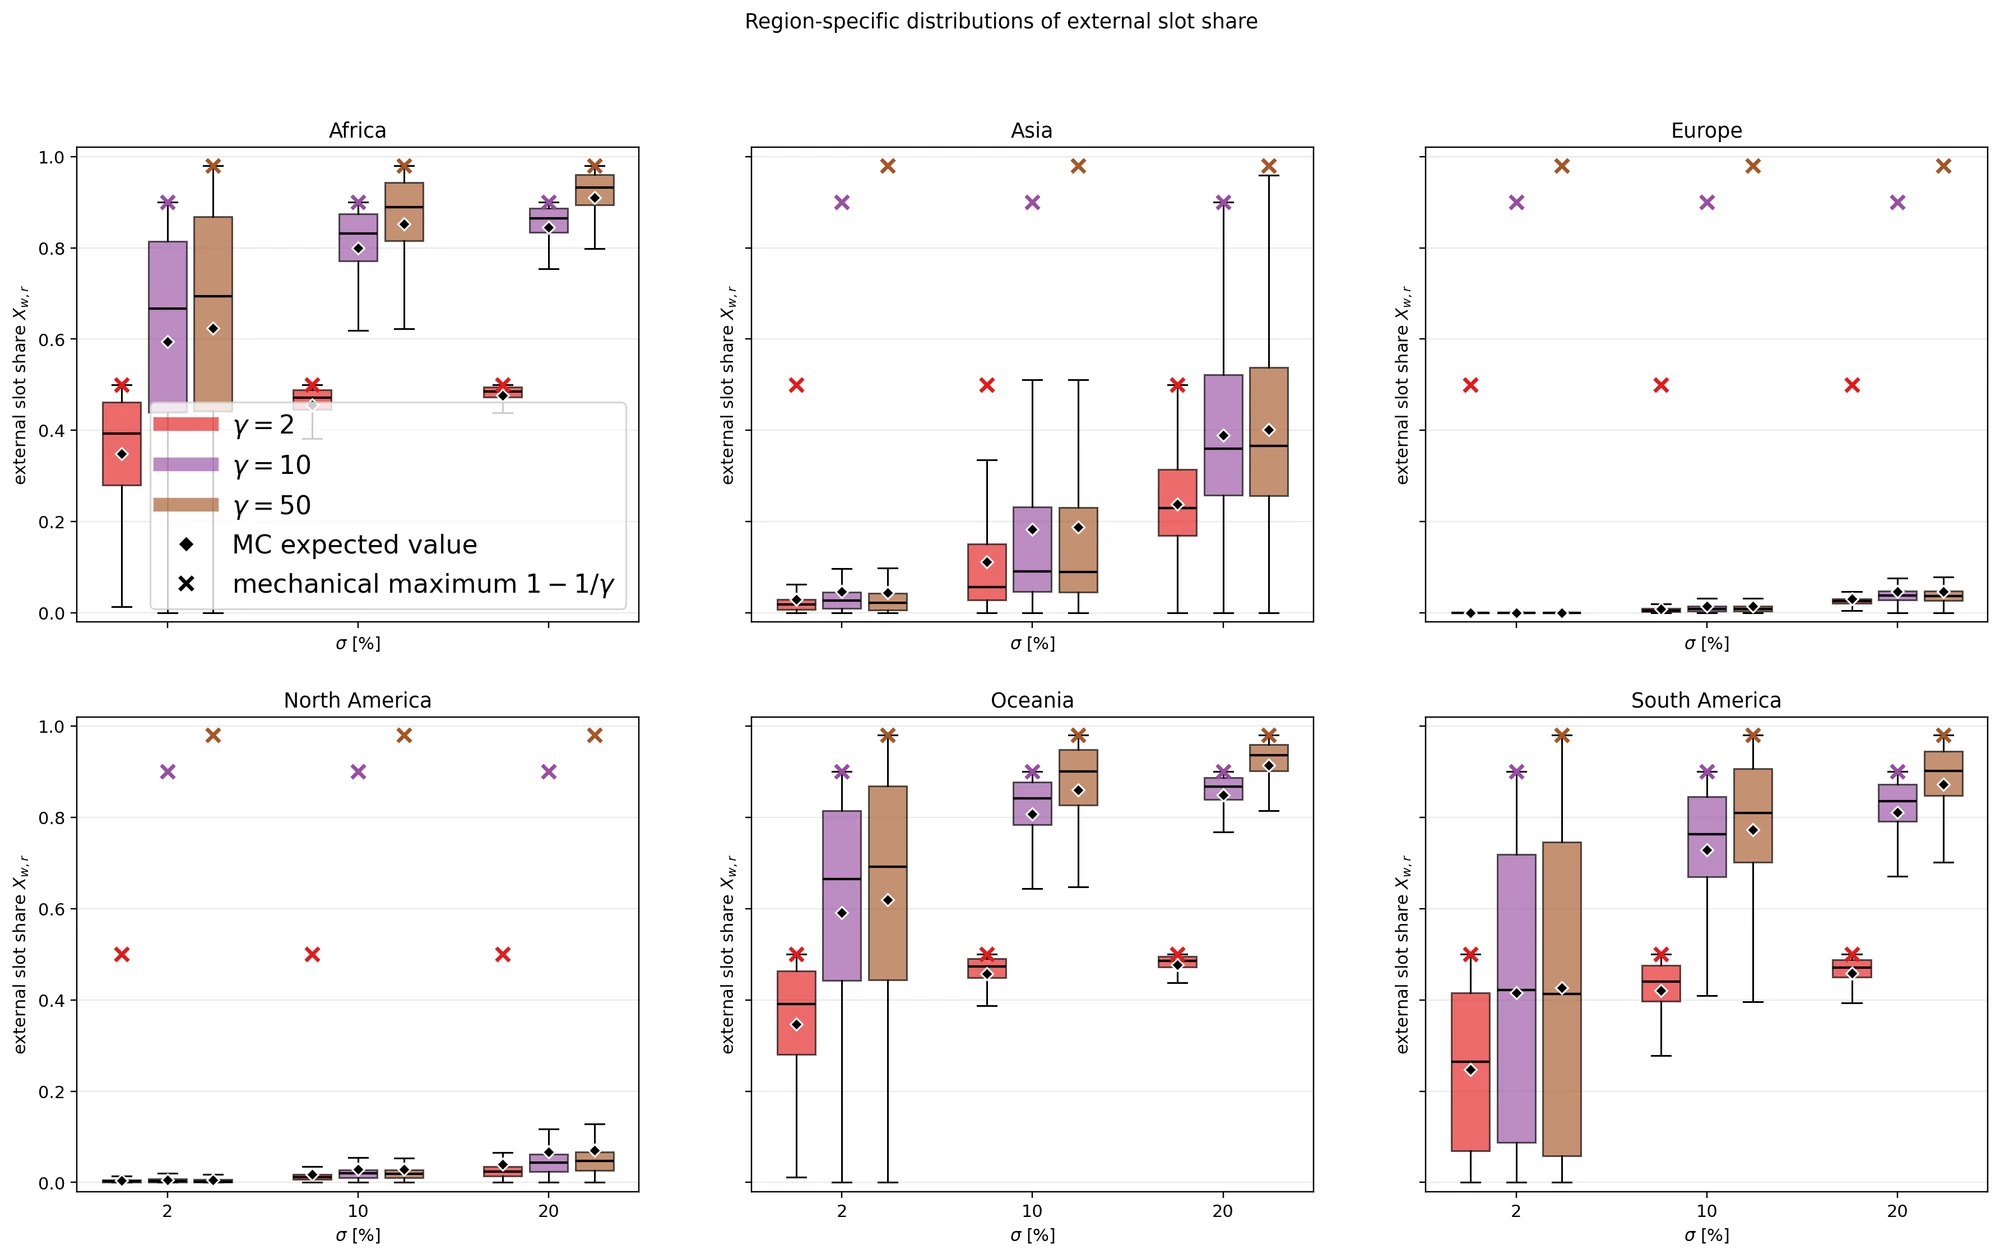
Fig. 7: Distribution of the external slot share across synthetic networks, by macroregion, and . Crosses mark the mechanical maximum .
Figure 7 shows what this means for each region under the current geography.
- Europe and North America are self-contained for every tested. Spillover stays at a few percent even at .
- Asia is the borderline case. At its bins are local. At the median is below 10%, but in some networks it reaches 50%. At its bins are mostly mixed. Asia's stake share is about 11% on average across synthetic networks and about 10.4% in today's snapshot, so sits just below it, with very little margin.
- Africa, Oceania and South America already have large spillover at and are close to the maximum at 10% and 20%. With one or two locations each, they hold too little stake for any reasonable .
Larger increases spillover in every region, because a bin has more slots to fill before it is emitted.
This gives the second side of the trade-off on . Persistence and concentration ask for a larger . Spillover asks for a below the stake of the smallest region we want to keep self-contained. Under today's geography that region is Asia, which puts around 10%. This conclusion depends directly on how much stake Asia holds, and should be revisited if it changes.
Fictitious Location Attack
Validators declare their own location, and the schedule trusts it. An actor that declares an isolated location can end up alone in its bins. Every complete bin it fills becomes a block of consecutive leader windows under its control.
If the stake declared at a location is at least , the radius of that location is zero. An honest leader can then join one of its bins only if its own radius reaches it, . In today's snapshot, an actor with 10% of stake at the isolated coordinate, in the South Pacific, at about , with , would be reachable only by validators in one Argentinian and one Australian location, holding together about 0.03% of the stake. Their radius reaches the actor precisely because the actor's own stake is the closest 10% they can find. In practice, its bins would contain only its own windows.
In a random schedule, a given block of consecutive windows belongs entirely to the attacker with probability . With and this is : it essentially never happens.
We have already seen that increasing concentrates long run in the same macroregion. This is logically true for single attacker of stake .
What we want to measure now is the gain when the attacker declare a fictitious location. Precisely, we consider an attacker who controls a total stake and declares a single coordinate as far as possible from every observed location. Honest stake is rescaled to .
For each simulated world, comparisons use the same attacker stake \(X\) and the same baseline leader schedule.
Let indicate attacker control of leader window . Choose uniformly among attacker-controlled windows. Define
This is the remaining consecutive control from the selected window, including that window.
For each world we can define
and
where ranges over the sampled truthful locations. Both metrics are measured in leader windows; reported means subsequently average across Monte Carlo worlds.
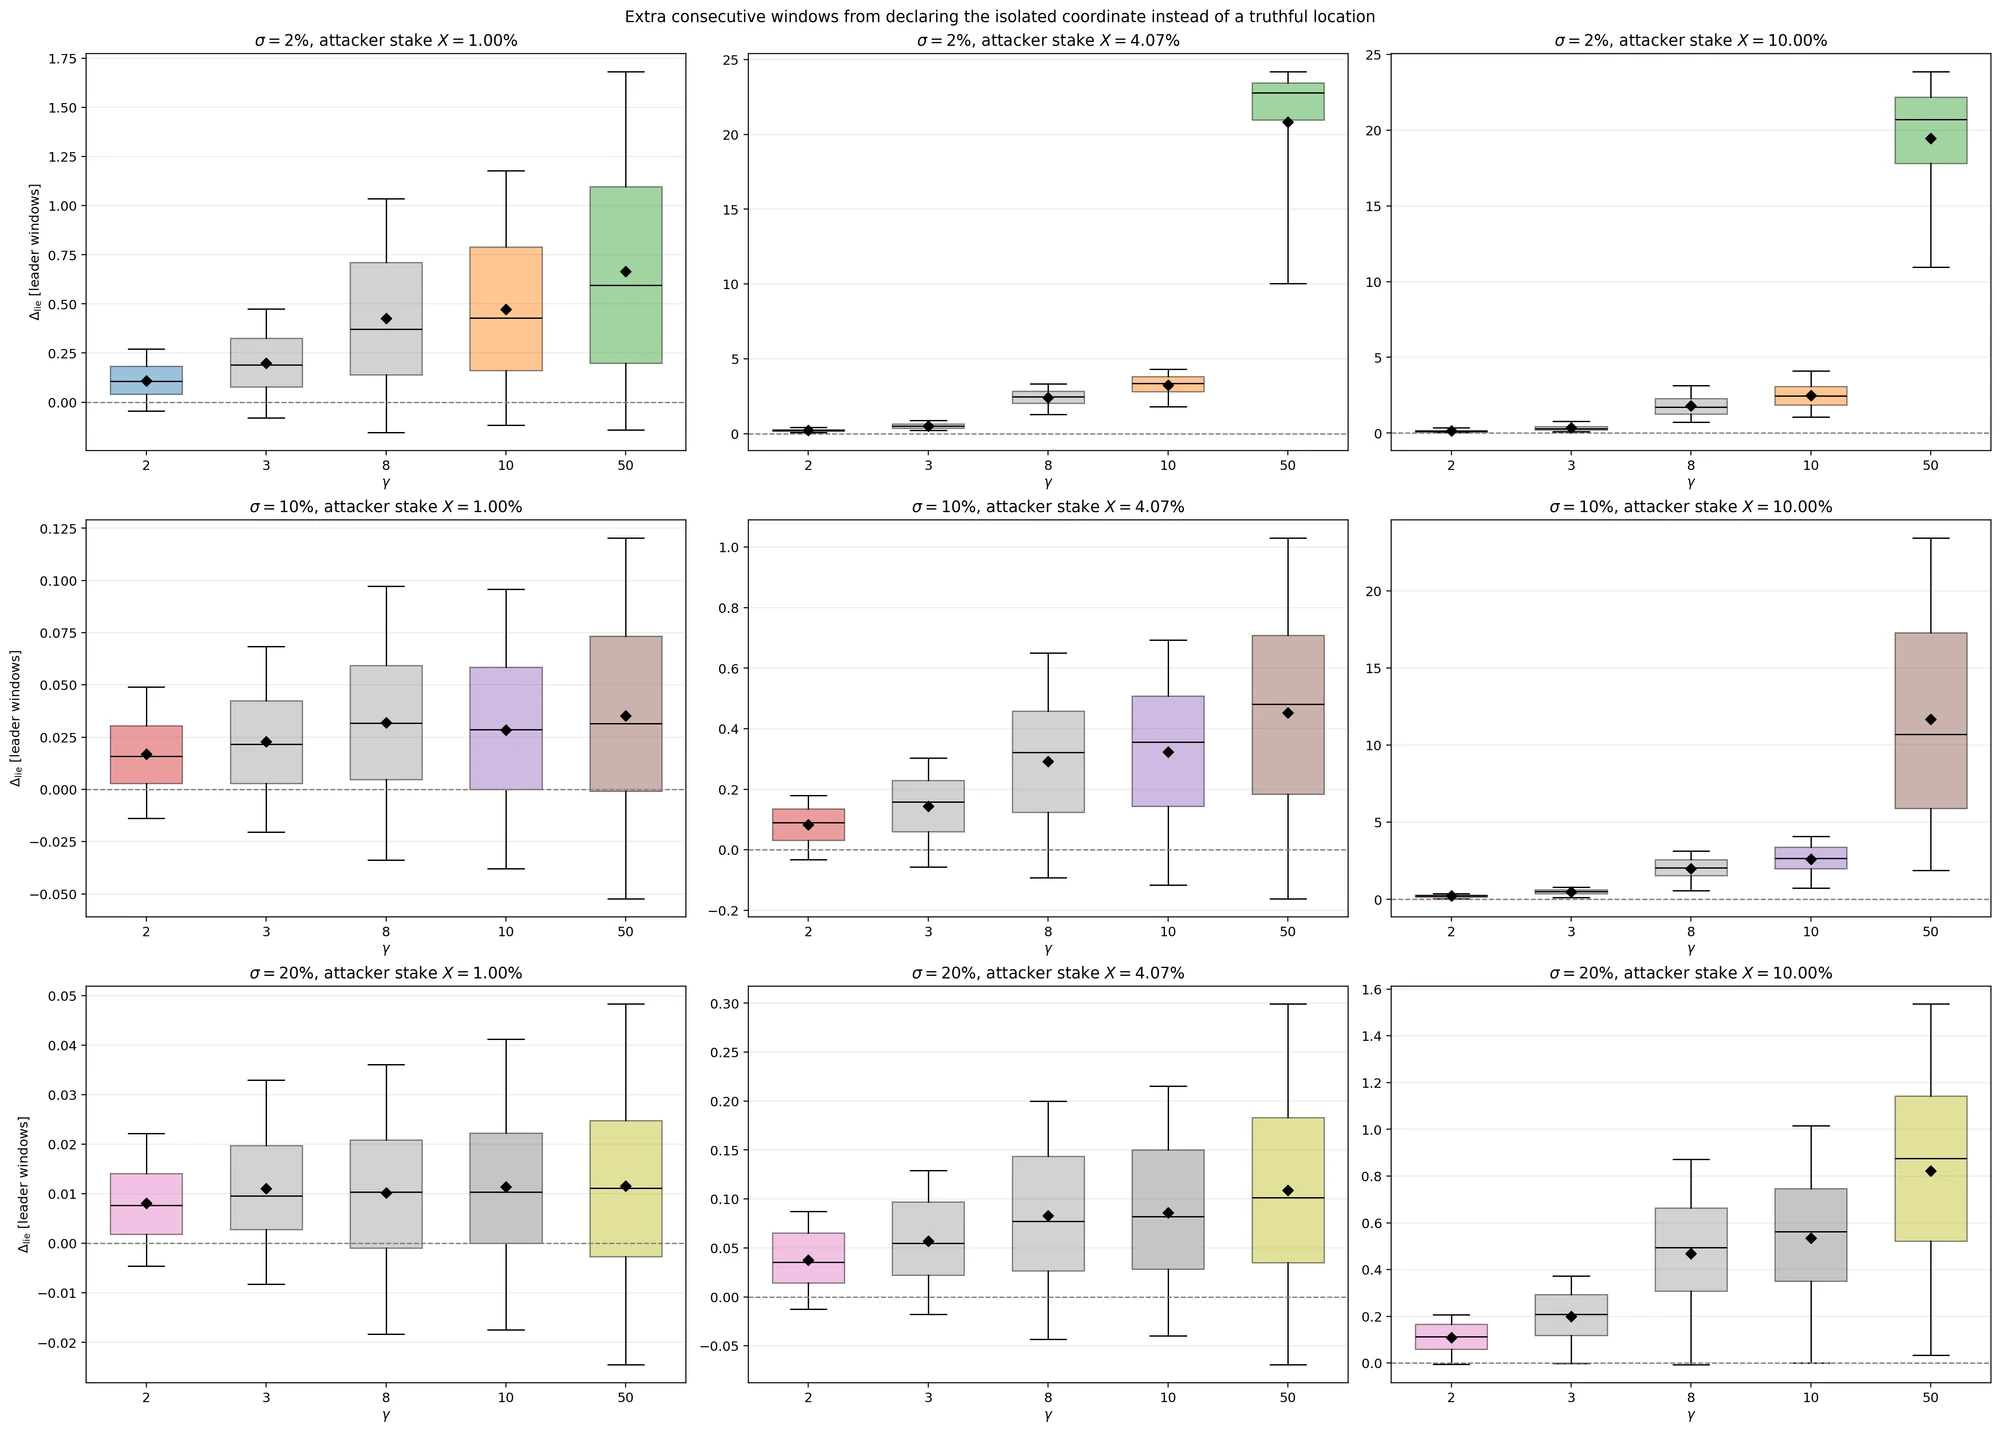
Fig. 8: Gain from lying about the location. Boxes span the interquartile range, the line is the median, whiskers are the 5th and 95th percentiles and diamonds the mean. Vertical scales differ between panels. Negative values mean the truthful location already yields longer runs than the isolated coordinate.
Figure 8 shows how the security threshold depends on the attacker’s stake. If the gain in expected slots starts to increase. It follows that this type of attack is discouraged when is as high as possible.
It is worth noting that, an high value of once is fixed tends to augument the gains of lying about the position.
Pareto Frontier and Geometrical Tradeoff
At this point, we have to observe that there is no configuration that maximizes the handoff gain and minimizes every risk at once. However, the analysis done so far can help us choose the two parameters.
Choosing the Stake Floor
Almost every risk we measured decreases as grows: persistence, short-horizon occupancy, bin dominance and coalition persistence. Only two things push the other way. The handoff gain is larger for small , and spillover sets a hard ceiling: as soon as a region holds less than of the stake, its bins stop being local (Fig. 6).
However, we have seen that is also controlling the size of the stake incentivized to misreport isolated coordinates. Thus, higher is higher is the stake needed to gain the incentive. In other words, you want to be as high as possible.
The tradeoff is then selecting the highest value of such that the smallest region with local bins today preserves the locality.
The smallest region with local bins today is Asia. Its stake share moved between 10.4% and 11.6% over epochs 1000–1041, and sits at 10.4% in the latest one.
We take the largest below that ceiling,
The price is latency: at , the mean gain is 29.8 ms at against 35.4 ms at . In exchange, every security metric improves. The margin to Asia's stake is small, so this value has to be revisited if Asia's share drops.
Choosing the Run Length
With fixed, both the gain and the risks grow with . Among the risks, regional occupancy matters little for this choice: over 5 minutes it is already indistinguishable from random for , and over 15 minutes for every , while outages typically last longer than that. What really changes is how long the network stays in one region without interruption.
Since gain and risk grow together, almost every value of at sits on the Pareto frontier. To find where the trade-off turns, we use the knee: the point that maximizes the normalized gain minus the normalized risk, measured from the random schedule to . Larger values of are shown, but are not candidates for the knee, because larger bins buy almost no latency.
Fig. 9: Mean handoff gain against mean excess geographic persistence , across synthetic networks. Every simulated is shown, colored by \sigma and sized by . The black line is the Pareto frontier at ; the star marks its knee, computed for .
Figure 9 shows the two curves behave very differently. The gain saturates quickly, while keeps growing almost linearly with . The frontier is steep for small and flat for large .
The knee is at . There the schedule gains 29.1 ms, 86% of the gain at , and has a mean cumulative persistence score of 5.4 extra windows (4.3 s) on average. Beyond that point latency becomes expensive. Going from to adds 1.7 ms for 2.7 extra windows; going to adds 4.8 ms for 35 extra windows. The tail of same-region runs gives almost the same answer: its knee is at , on a grid that does not include .
It is worth mentioning that, the knee depends on the largest it sees: normalizing on instead of moves it to , only because the far end of the frontier is pushed further out.
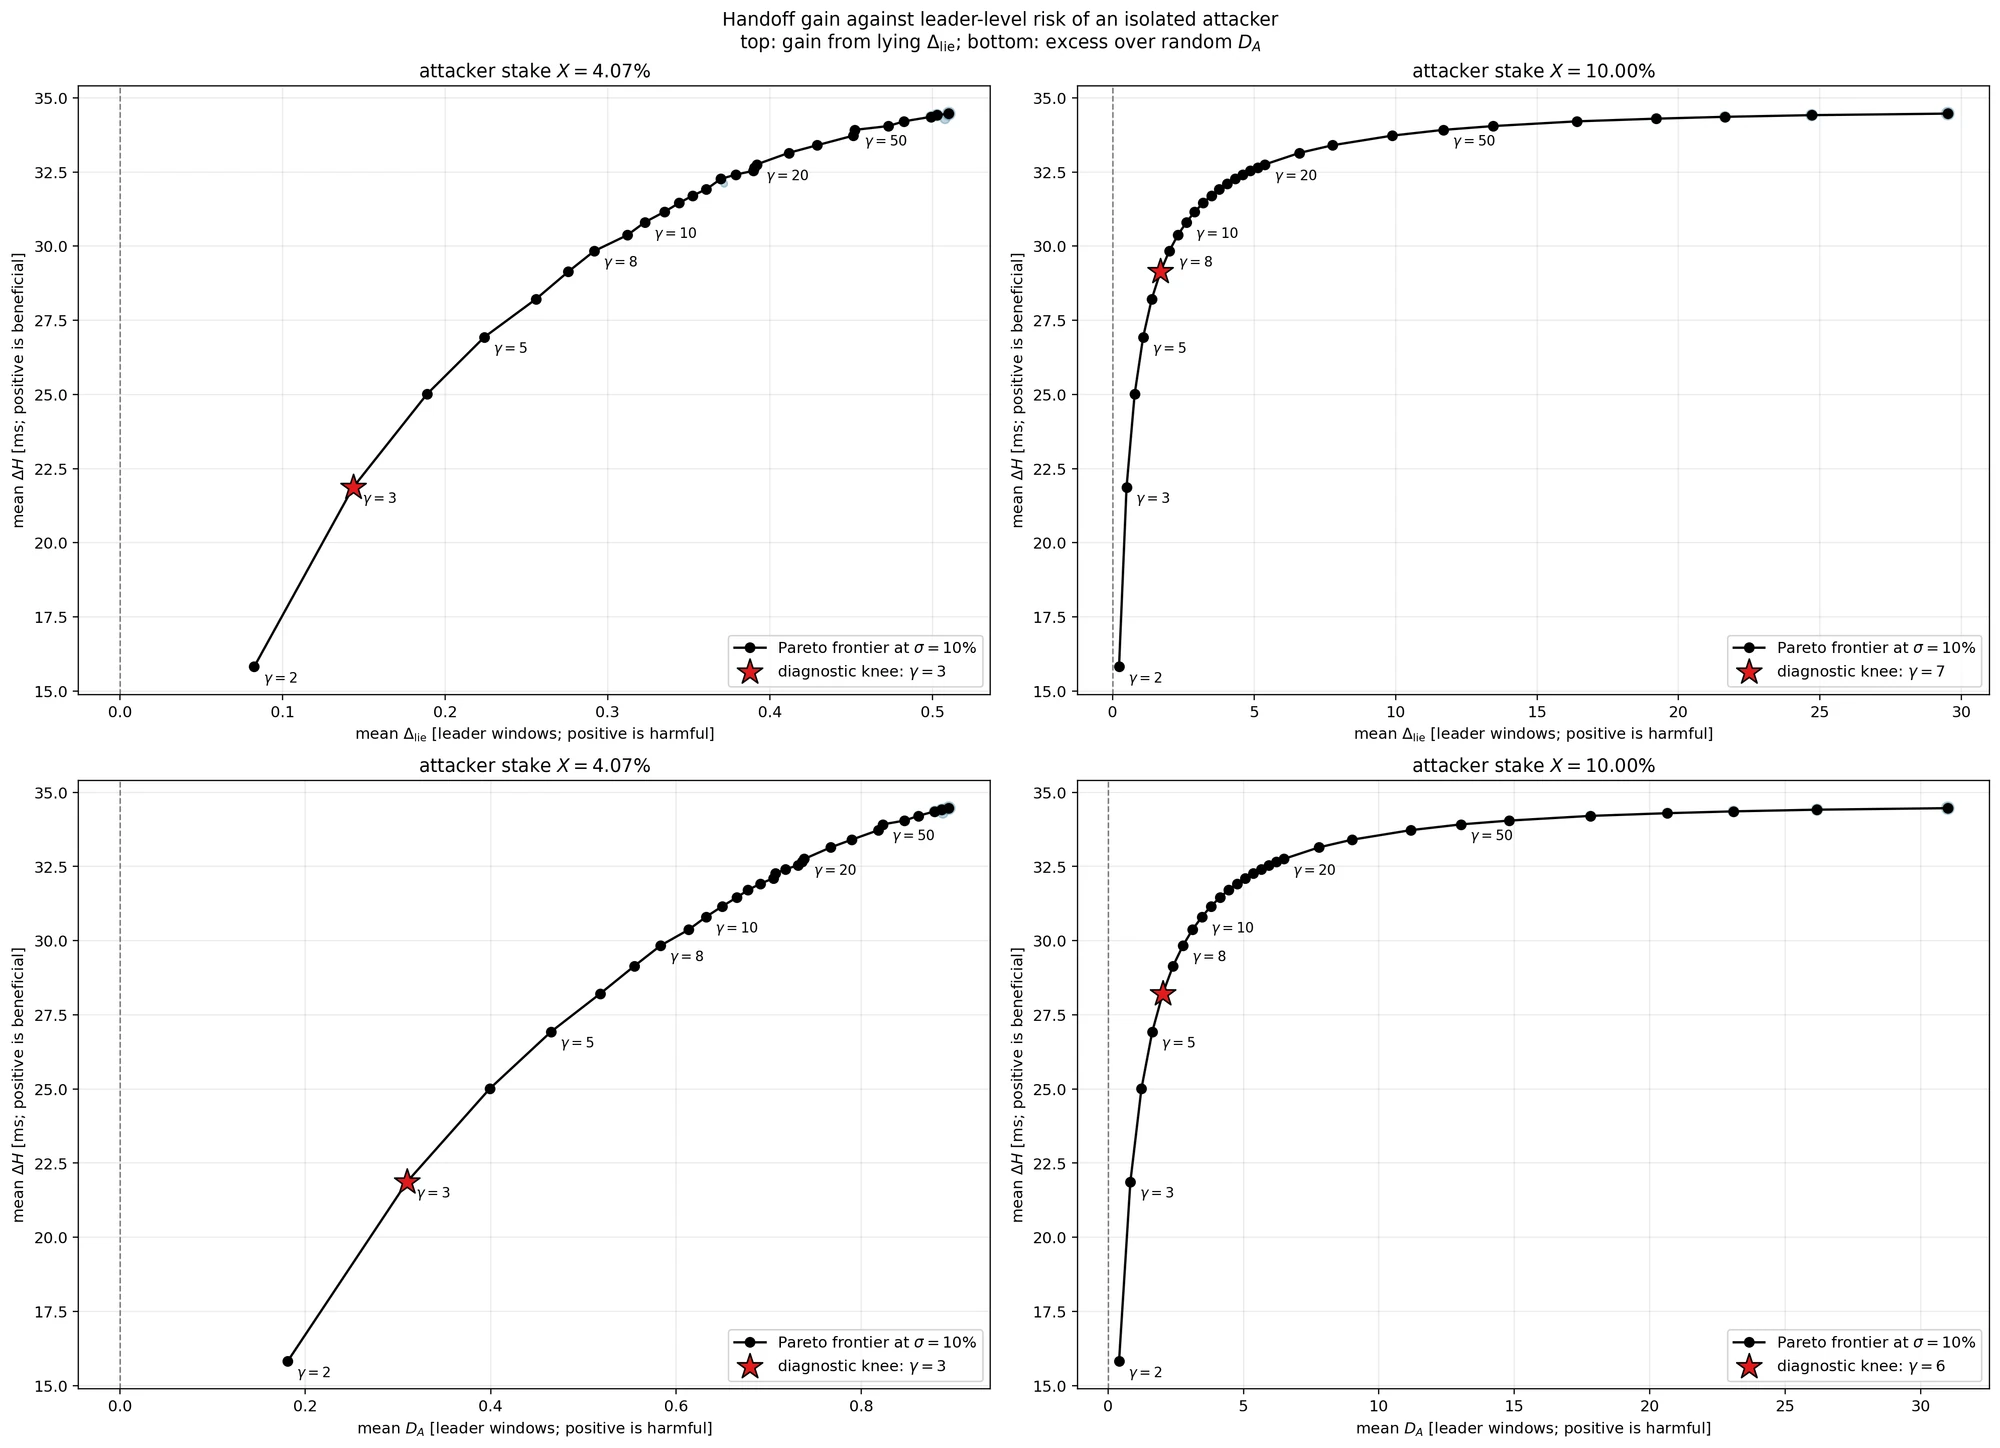
Fig. 10: Mean handoff gain against the leader-level risks of an isolated attacker, at . Top: gain from lying about the location, . Bottom: increase in expected remaining consecutive control, conditional on an attacker-controlled starting window, relative to random, . Left: attacker with the largest stake today, . Right: attacker at the stake floor, . The black line is the Pareto frontier; the star marks its knee, computed for .
In Fig. 10 we report the Pareto frontier and relative knee comparing mean handoff against the leader-level risks of an isolated attacker, fixing .
The knee only describes the shape of the frontier, not the level of the risk. At , lying is worth 0.28 windows to an attacker with 4.07% of stake, and 1.69 windows to an attacker with 10%.
Every knee falls between and . A value around sits on the knee of the regional risks and of an attacker at the stake floor, and keeps 86% of the achievable gain. A value represents the conservative choice if the priority is the exposure to single validators below : it keeps 65% of the gain.
Similar results hold under a second choice of priors for regional stake displacement. With the regional stake prior of Appendix B, where any macroregion can hold the largest share of stake, the knee against stays at and the knees for an attacker at are at for both risks. For an attacker below , the knee against stays at and the one against moves to , where the risk is only 0.03 windows.
Pricing Every Millisecond
So far we have chosen the parameters through knees. That works for , much less for .
When reasoning about , we have that it is boxed in from both sides. It has to be larger than the stake of any actor that could profit from a fictitious location, and smaller than the stake of the smallest macroregion we want to keep local. Today these bounds leave a narrow range around 10%.
The parameter doesn’t share the same feature. The risks grow steadily with , while the gain of each extra step shrinks quickly, so the frontiers have no natural break point. The knee we used only appears once we pick an end for the frontier: with the largest at 20, 50 or 200, the knee against falls at , 7 or 14. Any single value of read off a knee is therefore partly a product of the grid.
Instead of fixing parameters, we can show what each millisecond of handoff gain costs, and let the reader decide how much risk a millisecond is worth.
All risks in this analysis are counted in leader windows: extra consecutive windows in the same macroregion (), or held by an attacker (, ). One window is four 200 ms slots, so each risk converts directly to milliseconds. For every and every step we then compute
the milliseconds of risk paid for each millisecond of handoff gain. The first step starts from the random schedule, where both are zero.
The two milliseconds are not the same thing. A millisecond of handoff gain is saved at every change of leader, i.e. every 0.8 s. A millisecond of risk is an expected stretch of time spent in one region or under one leader. The price tells us how fast one grows compared with the other, not that they are worth the same.
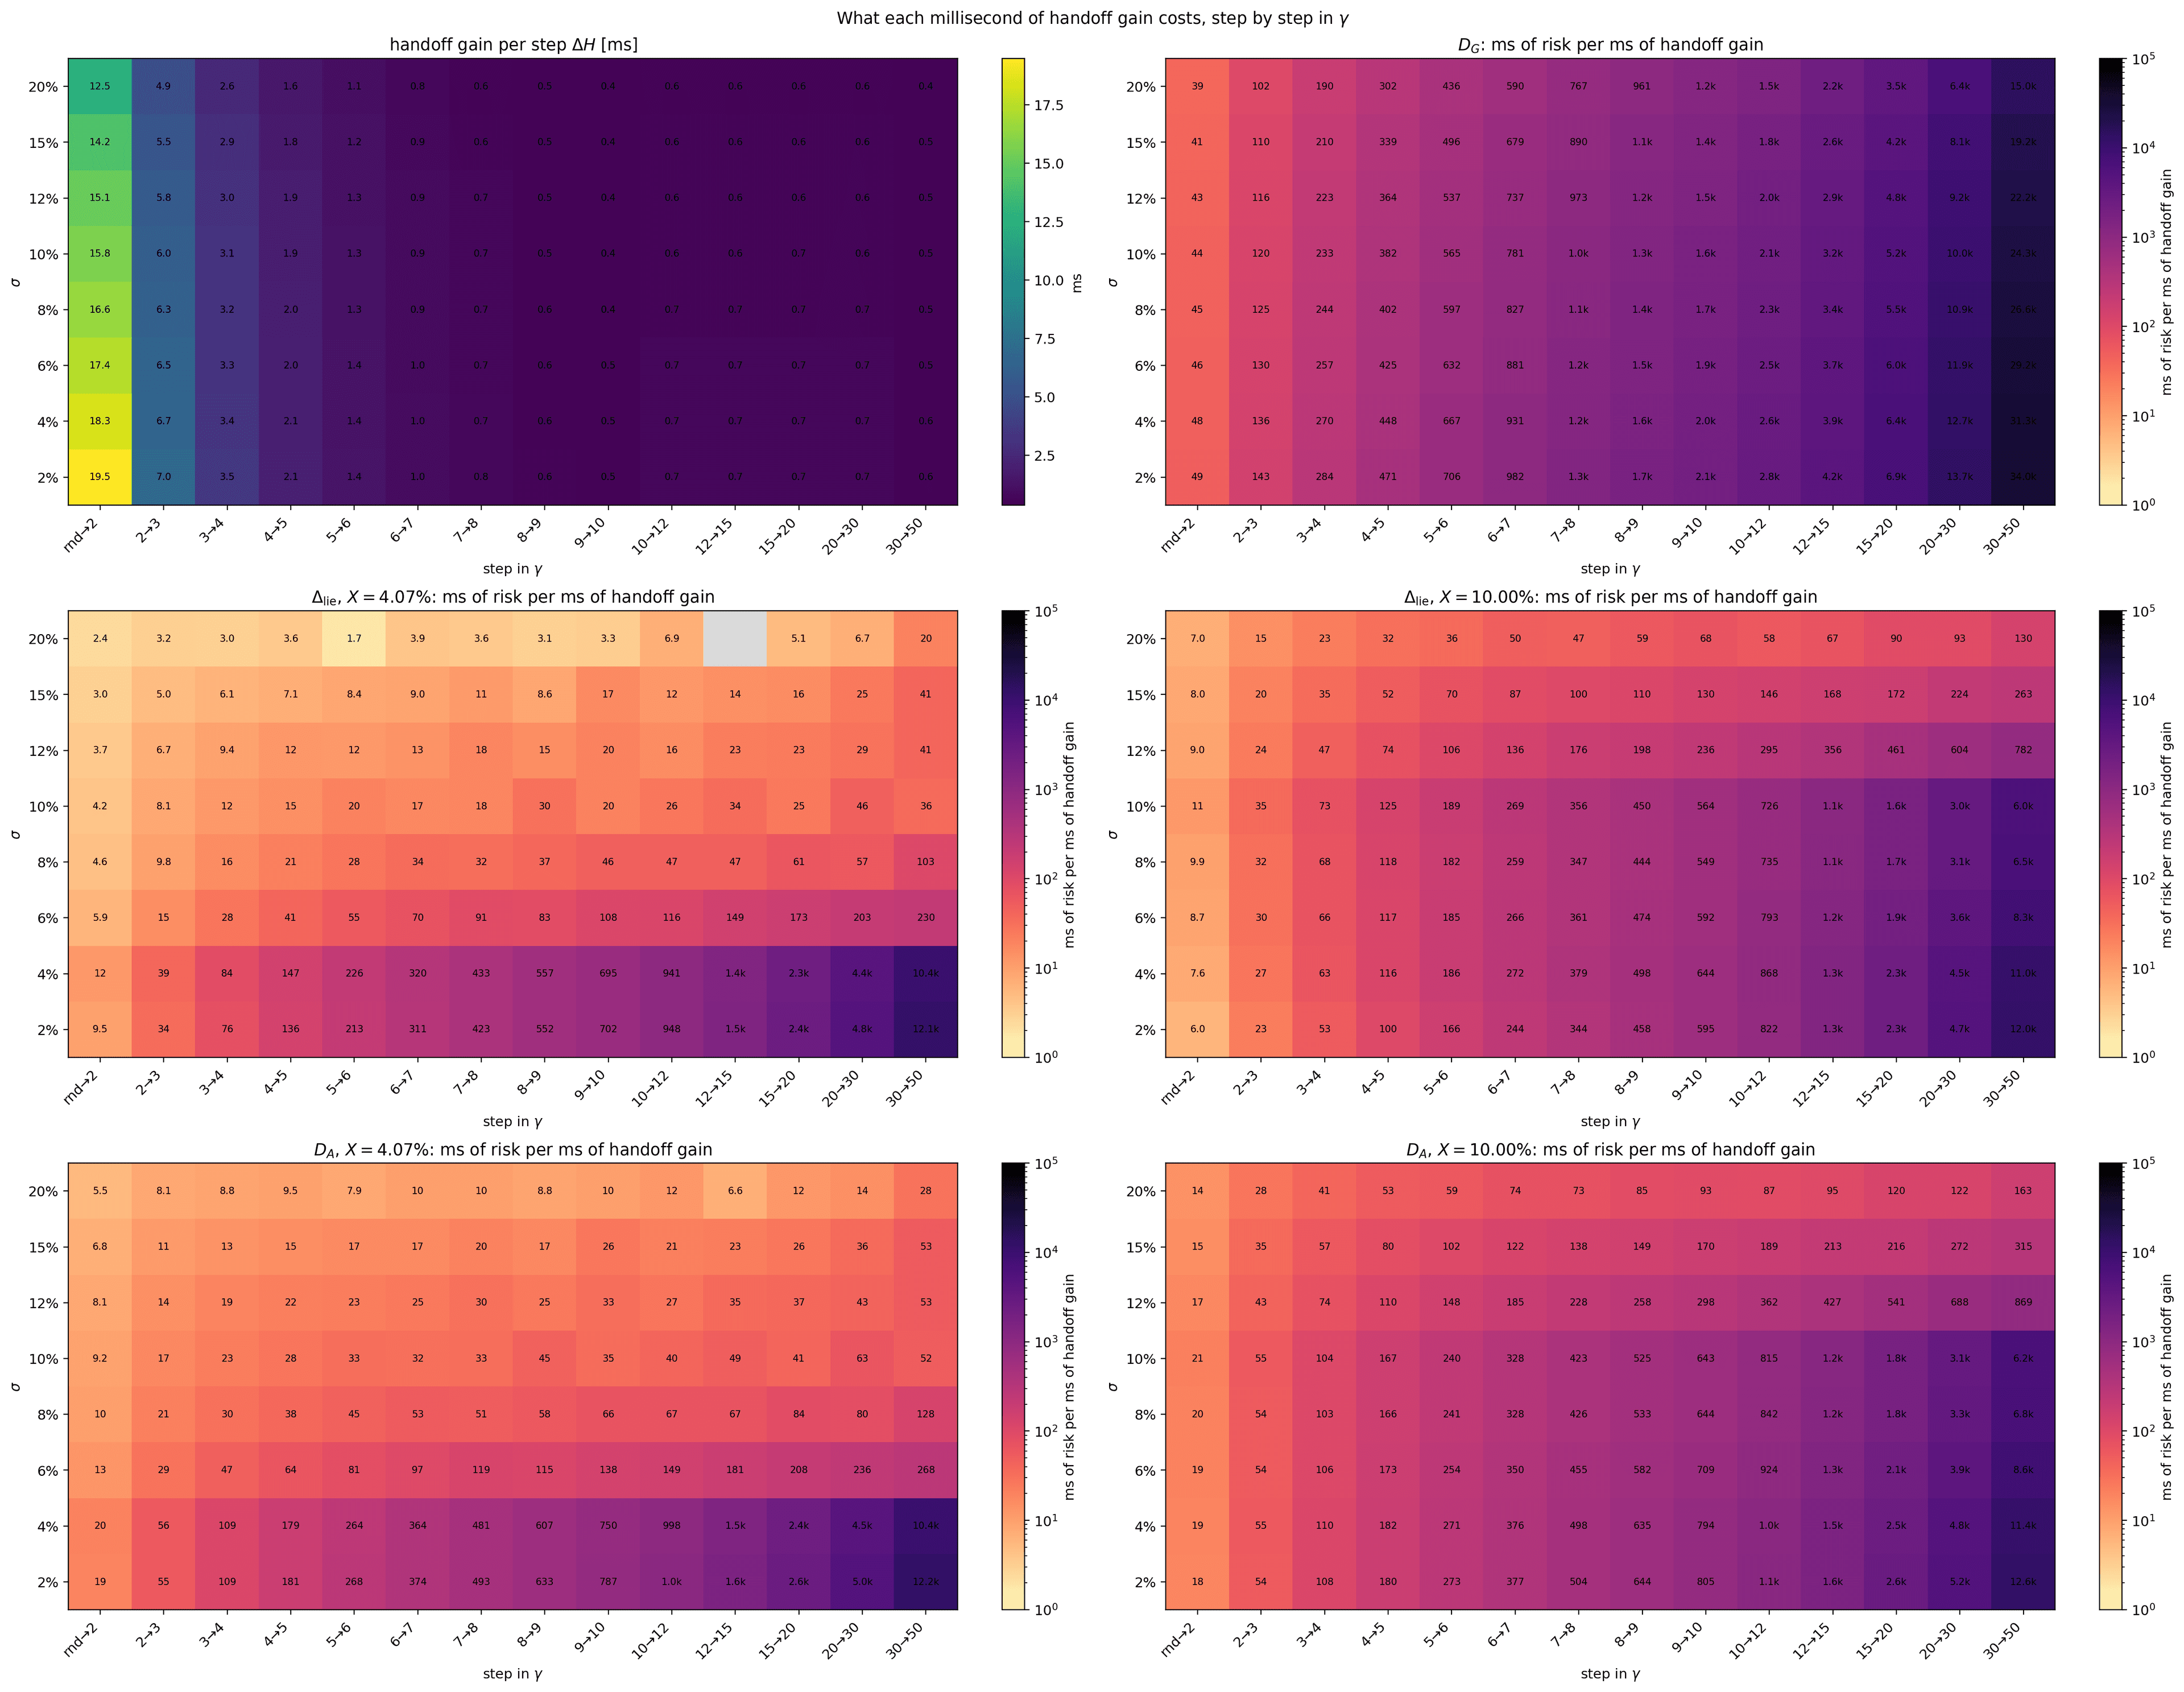
Fig. 11: Top left: handoff gain of each step in by . Other panels: milliseconds of risk paid for each millisecond of handoff gain, for , and for \ and with an attacker at (the largest validator today) and . Log color scale; grey cells are steps where the risk does not grow.
The result in Fig. 11 turns the choice of into two simple questions: which risk do we care about most, and what is the highest price we accept for a millisecond?
Once the price of a step goes above that limit, every later step costs even more. Going further is never rational for that priority, so the limit sets a maximum .
Specifically, represents a candidate compromise, not a preference-independent optimum. At 7 the gain start to saturate. Above 7, the geographic persistence costs 1s for every ms gained. If this is the maximum cost we are willing to pay for extra ms in handoffs, represents our maximum.
Below the choice depends on the priority. Accepting the average price leads to . A stricter price leads to a smaller : about 500 ms per ms for regional persistence gives , 250 ms per ms gives , and protecting validators below gives .
The rational choice is therefore a range rather than a point. stays close to 10%, fixed by the stake of the largest actors and the size of the smallest local region. lies between 3 and 7, and where it sits in that range depends only on the price we put on a millisecond of handoff.
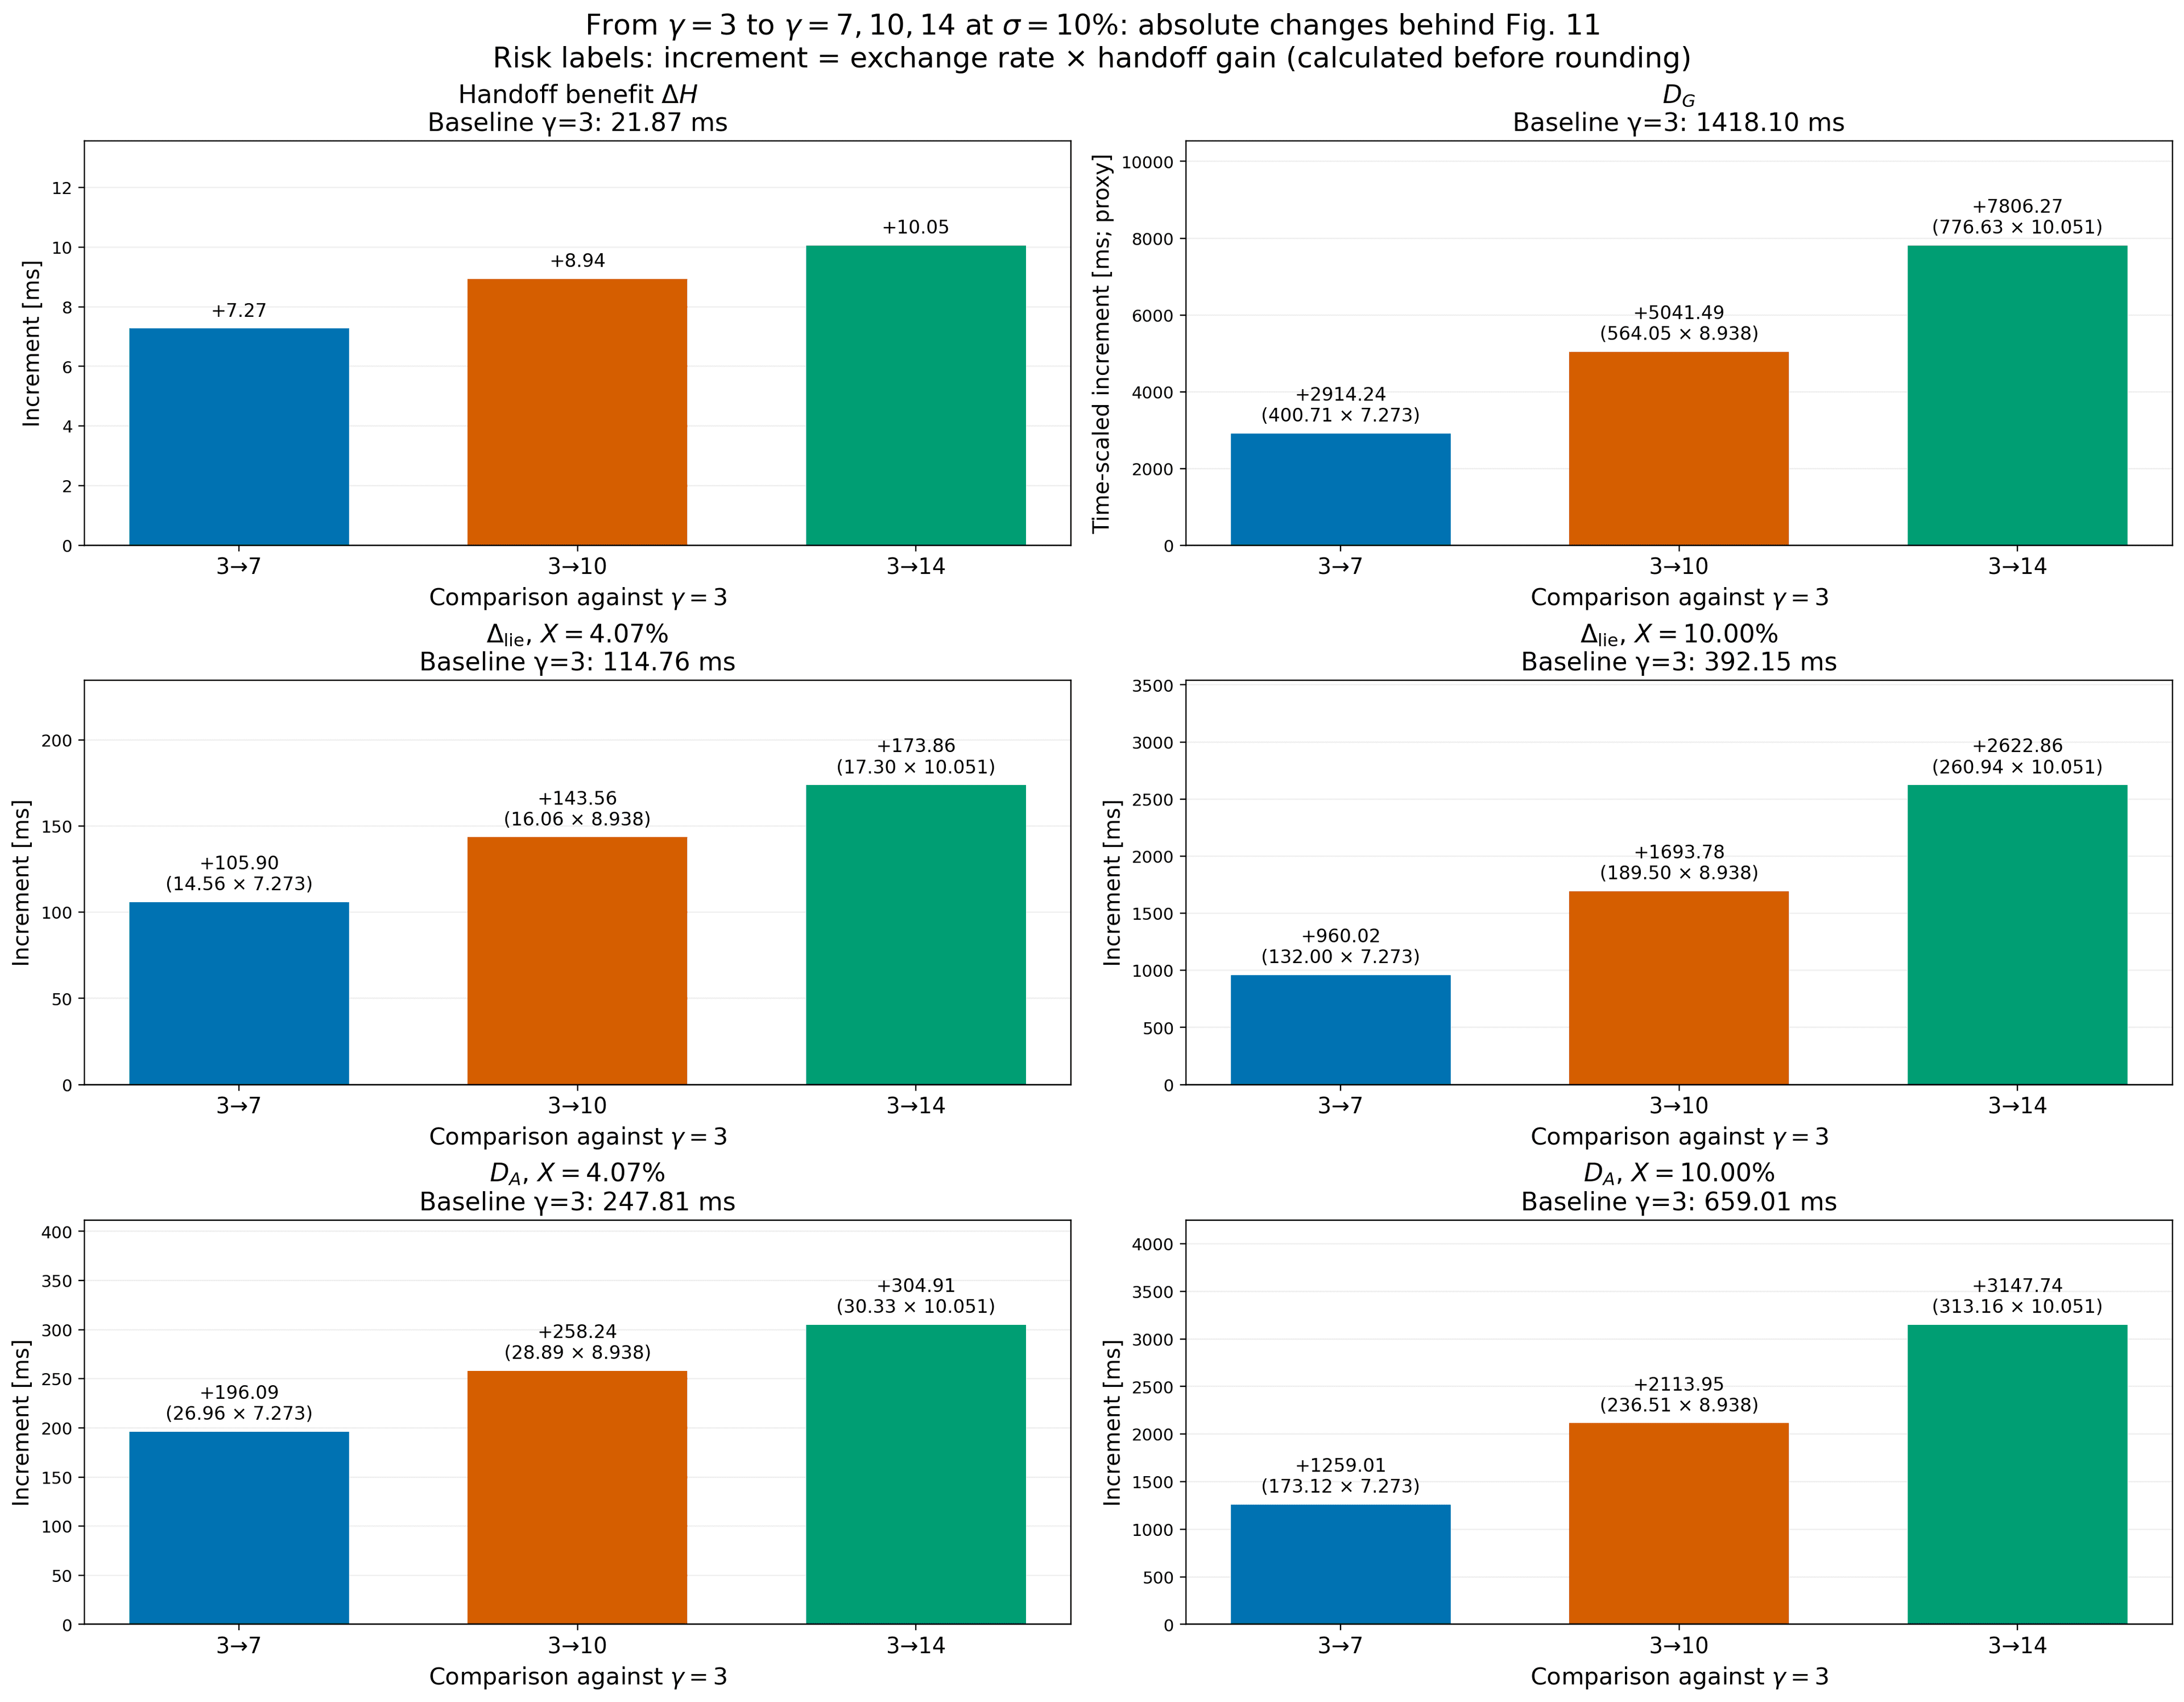
Fig. 12: Handoff improvements and risk increase moving from .
Appendix
Appendix A - MC Methodology
The core of this analysis is to provide an assessment of parameters implications that is as much as possible independent from current network snapshots. This is because an analysis done over a fixed stake distribution risks to introduce some dependencies on the peculiar configuration we measure today.
For this reason we implement a MC simulation with the following prescription
-
We define a factorial grid of Gini coefficients
-
For every Gini pair, we generate 250 independent network realizations, giving 6,250 synthetic networks.
-
Uniform integer prior for number of nodes in [400,2000]
-
Validator-location probabilities are generated from lognormal weights. Their dispersion is calibrated to the target node Gini through
Validator are then allocated across the observed geographical support
- Validator stakes are generated independently using the same Gini-controlled lognormal construction and normalized to sum to one.
At this point, for each realization we can extract a baseline schedule of slots, which is sampled proportional to stake (current version). We then study every point into the MC under variations.
The reason why we used a Gini coefficient structure for stake and node simulations is that stake and nodes tend to cluster. Further, low values of Gini can also accomodate more uniform distributions. Few samples are displayed below.
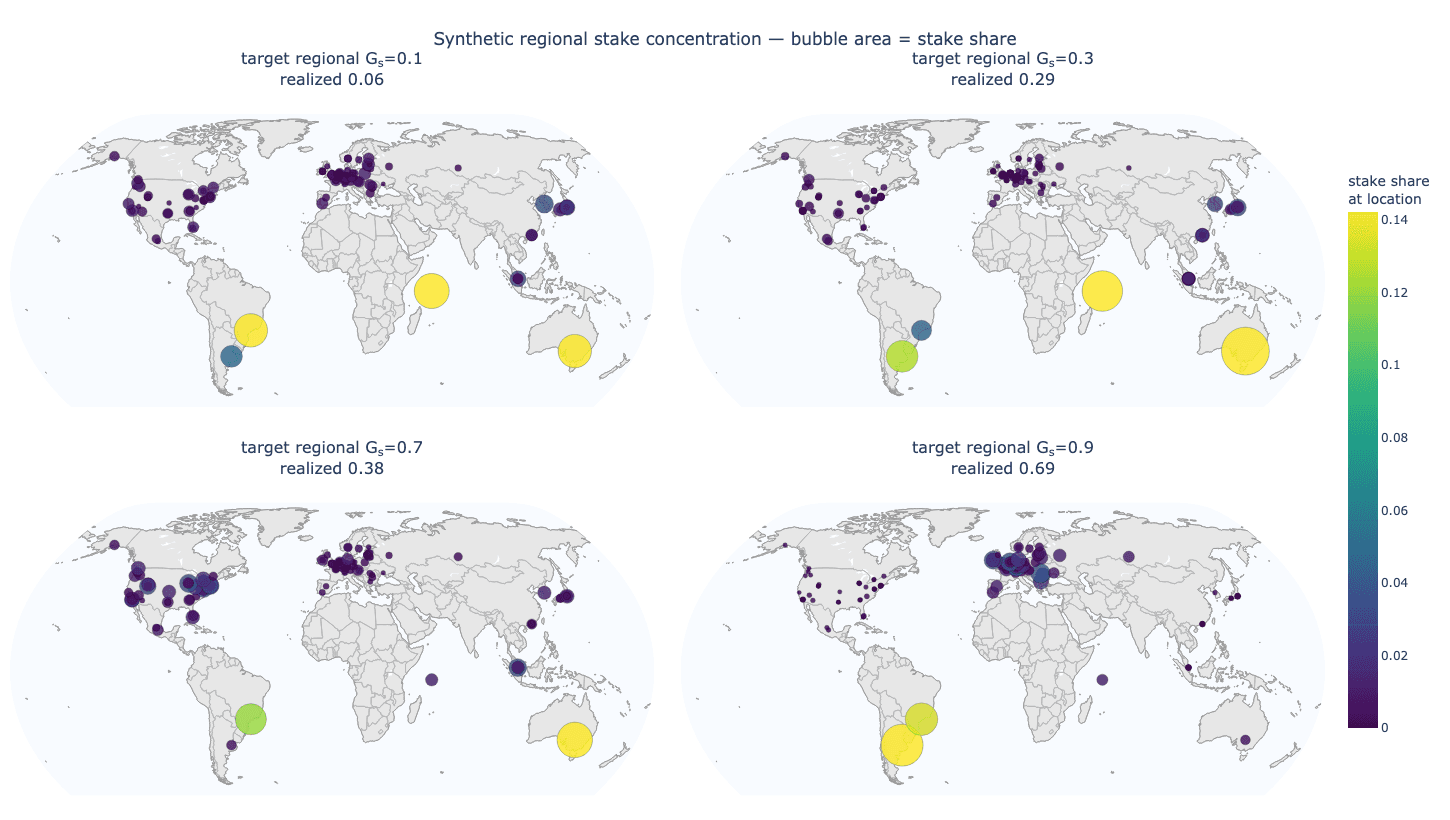
Fig. A1: Examples of regional stake distributions generated by the Gini priors for nodes and stake.
It is worth noting that, the use of Gini does not remove every dependence on the observed snapshot. The geographical support is fixed to 124 observed locations and is highly unbalanced across macroregions: Africa and Oceania contain one support point each, South America two, Asia fourteen, North America forty-two, and Europe sixty-four.
Since location weights are exchangeable across support points, expected regional mass is approximately proportional to the number of available support points. The simulation therefore does not model new locations, regional expansion, or migration beyond the observed support.
Further, there is a prior-sensitivity limitation. Despite the current snapshot, and node / stake evolution over time on every blockchain highly justify the choice of priors, the reported results might be prior-dependent.
All conclusions must therefore be interpreted as conditional on this generative model. In particular, the Monte Carlo cannot establish a parameter choice that is universally snapshot-independent.
Appendix B - A Random Stake Displacement
In the main Monte Carlo, the stake of a macroregion roughly follows the number of datacenters it hosts. Europe and North America hold most of it, Asia sits around 10–11%, and Africa, Oceania and South America stay small in every network. Here we drop that link and let stake move freely across the world.
The construction is simple:
- every one of the 124 observed locations hosts one validator, so the number of nodes plays no role;
- the stake of each macroregion comes from lognormal weights calibrated to a target Gini . The six weights are drawn independently, so any region can end up with the largest share;
- inside a macroregion, stake is split across its datacenters with a flat Dirichlet, i.e. every split is equally likely;
- coalitions are generated as in the main analysis.
Fig. B1: Examples of regional stake distributions generated by the Gini prior.
We generate 1,250 networks (5 stake Gini x 5 coalition Gini x 50 replicas), each with 108,000 leader windows, and run a smaller grid of parameters:
- , plus for the frontiers;
- .
With only six regions, the realized Gini falls below its target, and the two most concentrated cells (0.7 and 0.9) end up very similar. In this setup every region, Asia included, holds less than 10% of the stake in about one network out of three.
The main result is that the picture does not change. The same features that drive the main analysis are still there.
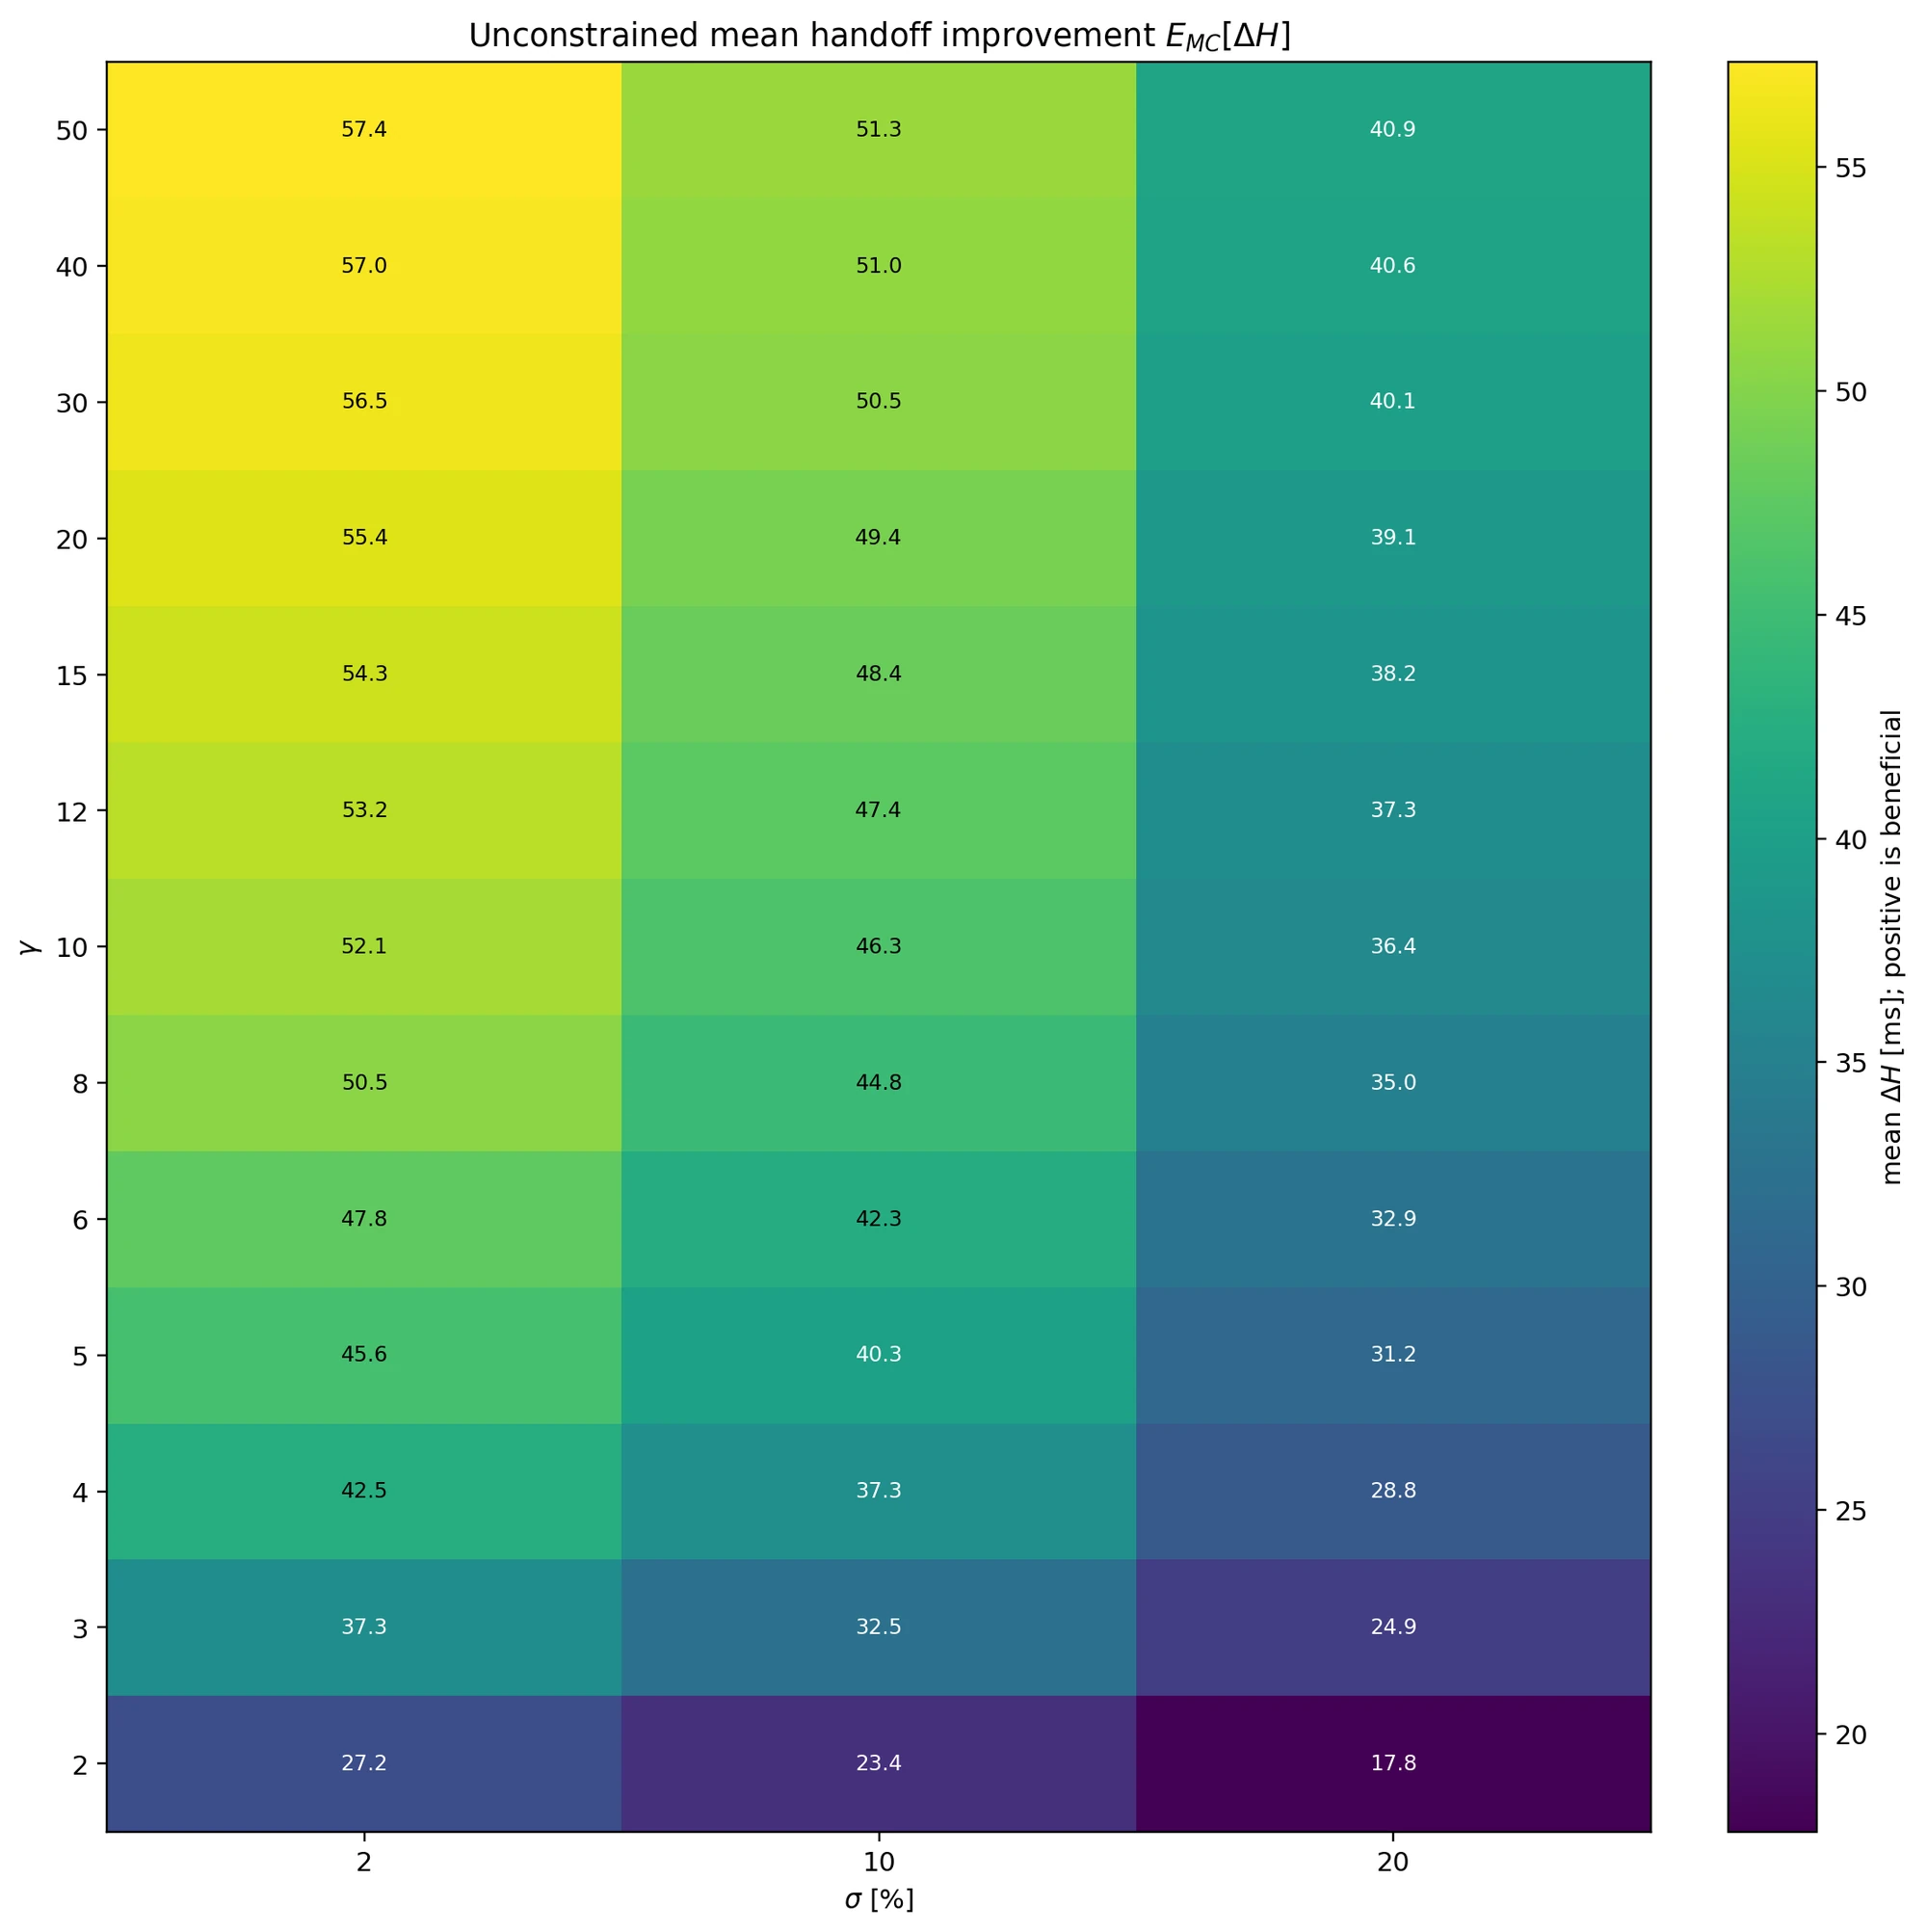
Fig. B2: Mean handoff gain across all synthetic networks in the simulations, for every parameter selection.
Handoff gain and persistence behave as before. Both grow with and the gain saturates around . The gain is larger, because with stake spread across continents a random schedule jumps between regions more often.
Persistence is lower: is 1.3, 5.7 and 26.7 windows for the same values of , against 1.8, 8.1 and 40.4 in the main analysis.
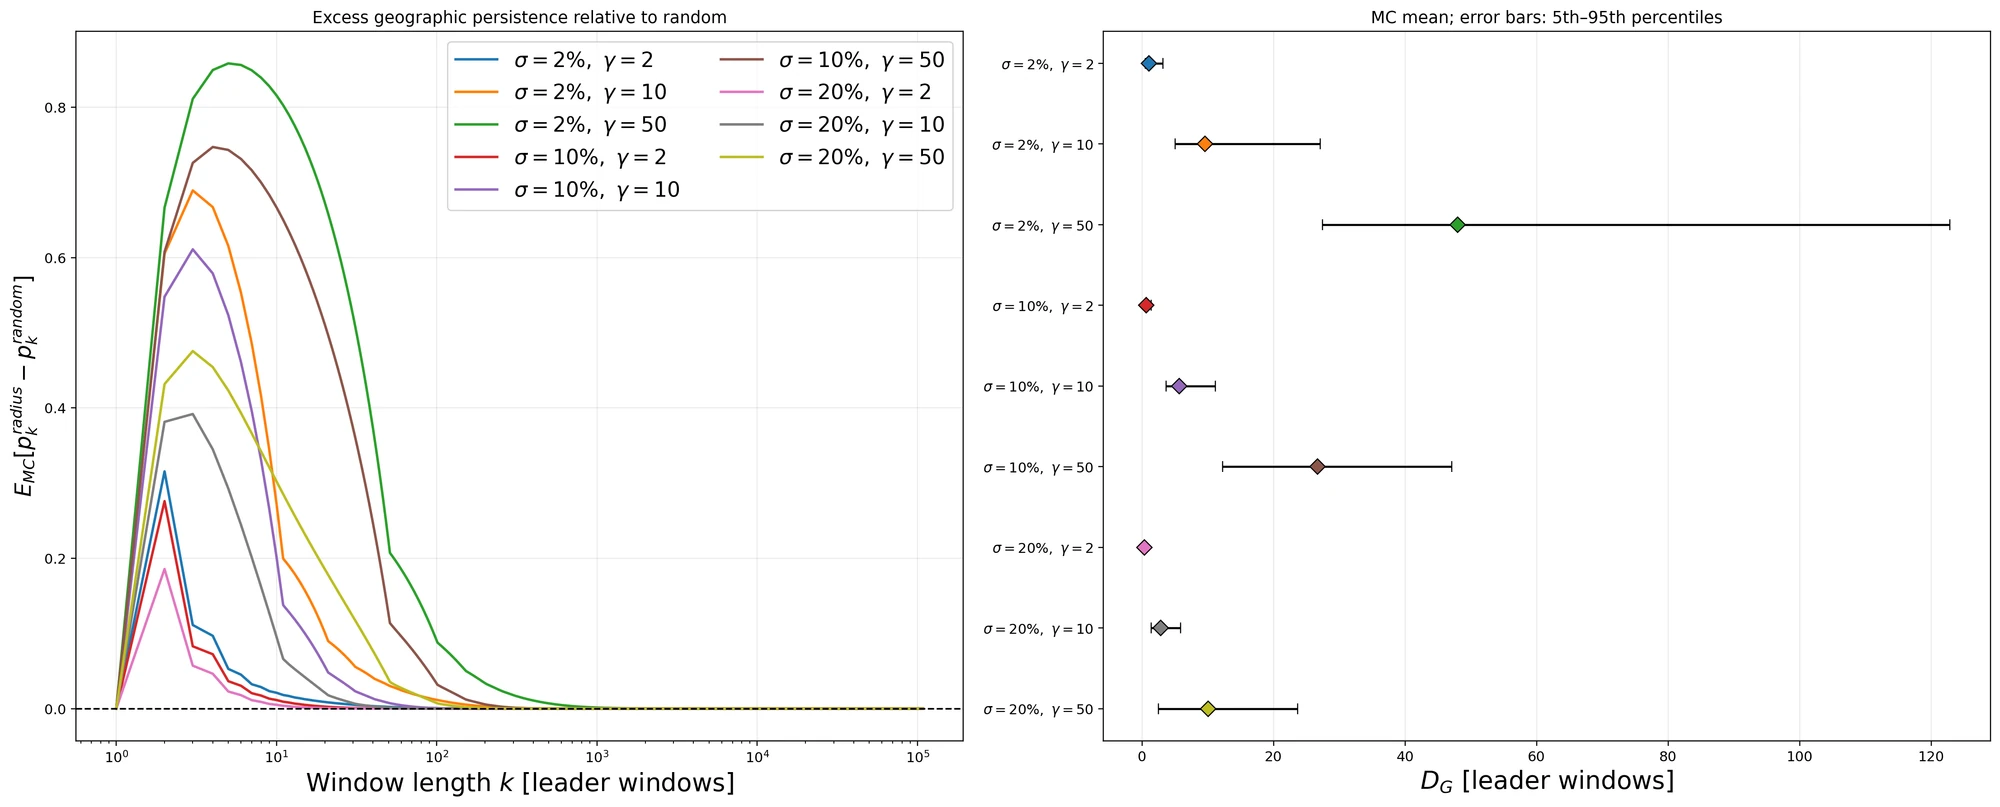
Fig. B3: Excess geographic persistence under the regional stake prior. Same layout as Fig. 3.
Lying about the location still pays only when the attacker's stake approaches . At :
| Attacker stake | |||
|---|---|---|---|
| 1% | 0.00 | 0.00 | 0.00 |
| 4.07% | 0.02 | 0.05 | 0.09 |
| 10% | 0.56 | 3.0 | 16.0 |
Below the gain is essentially zero: for the median is about zero and in half of the cases the truthful location already gives longer runs. At the attacker gains several windows, and the gain grows quickly with . So still sets the stake needed to make the attack worthwhile, and a larger still raises that bar.
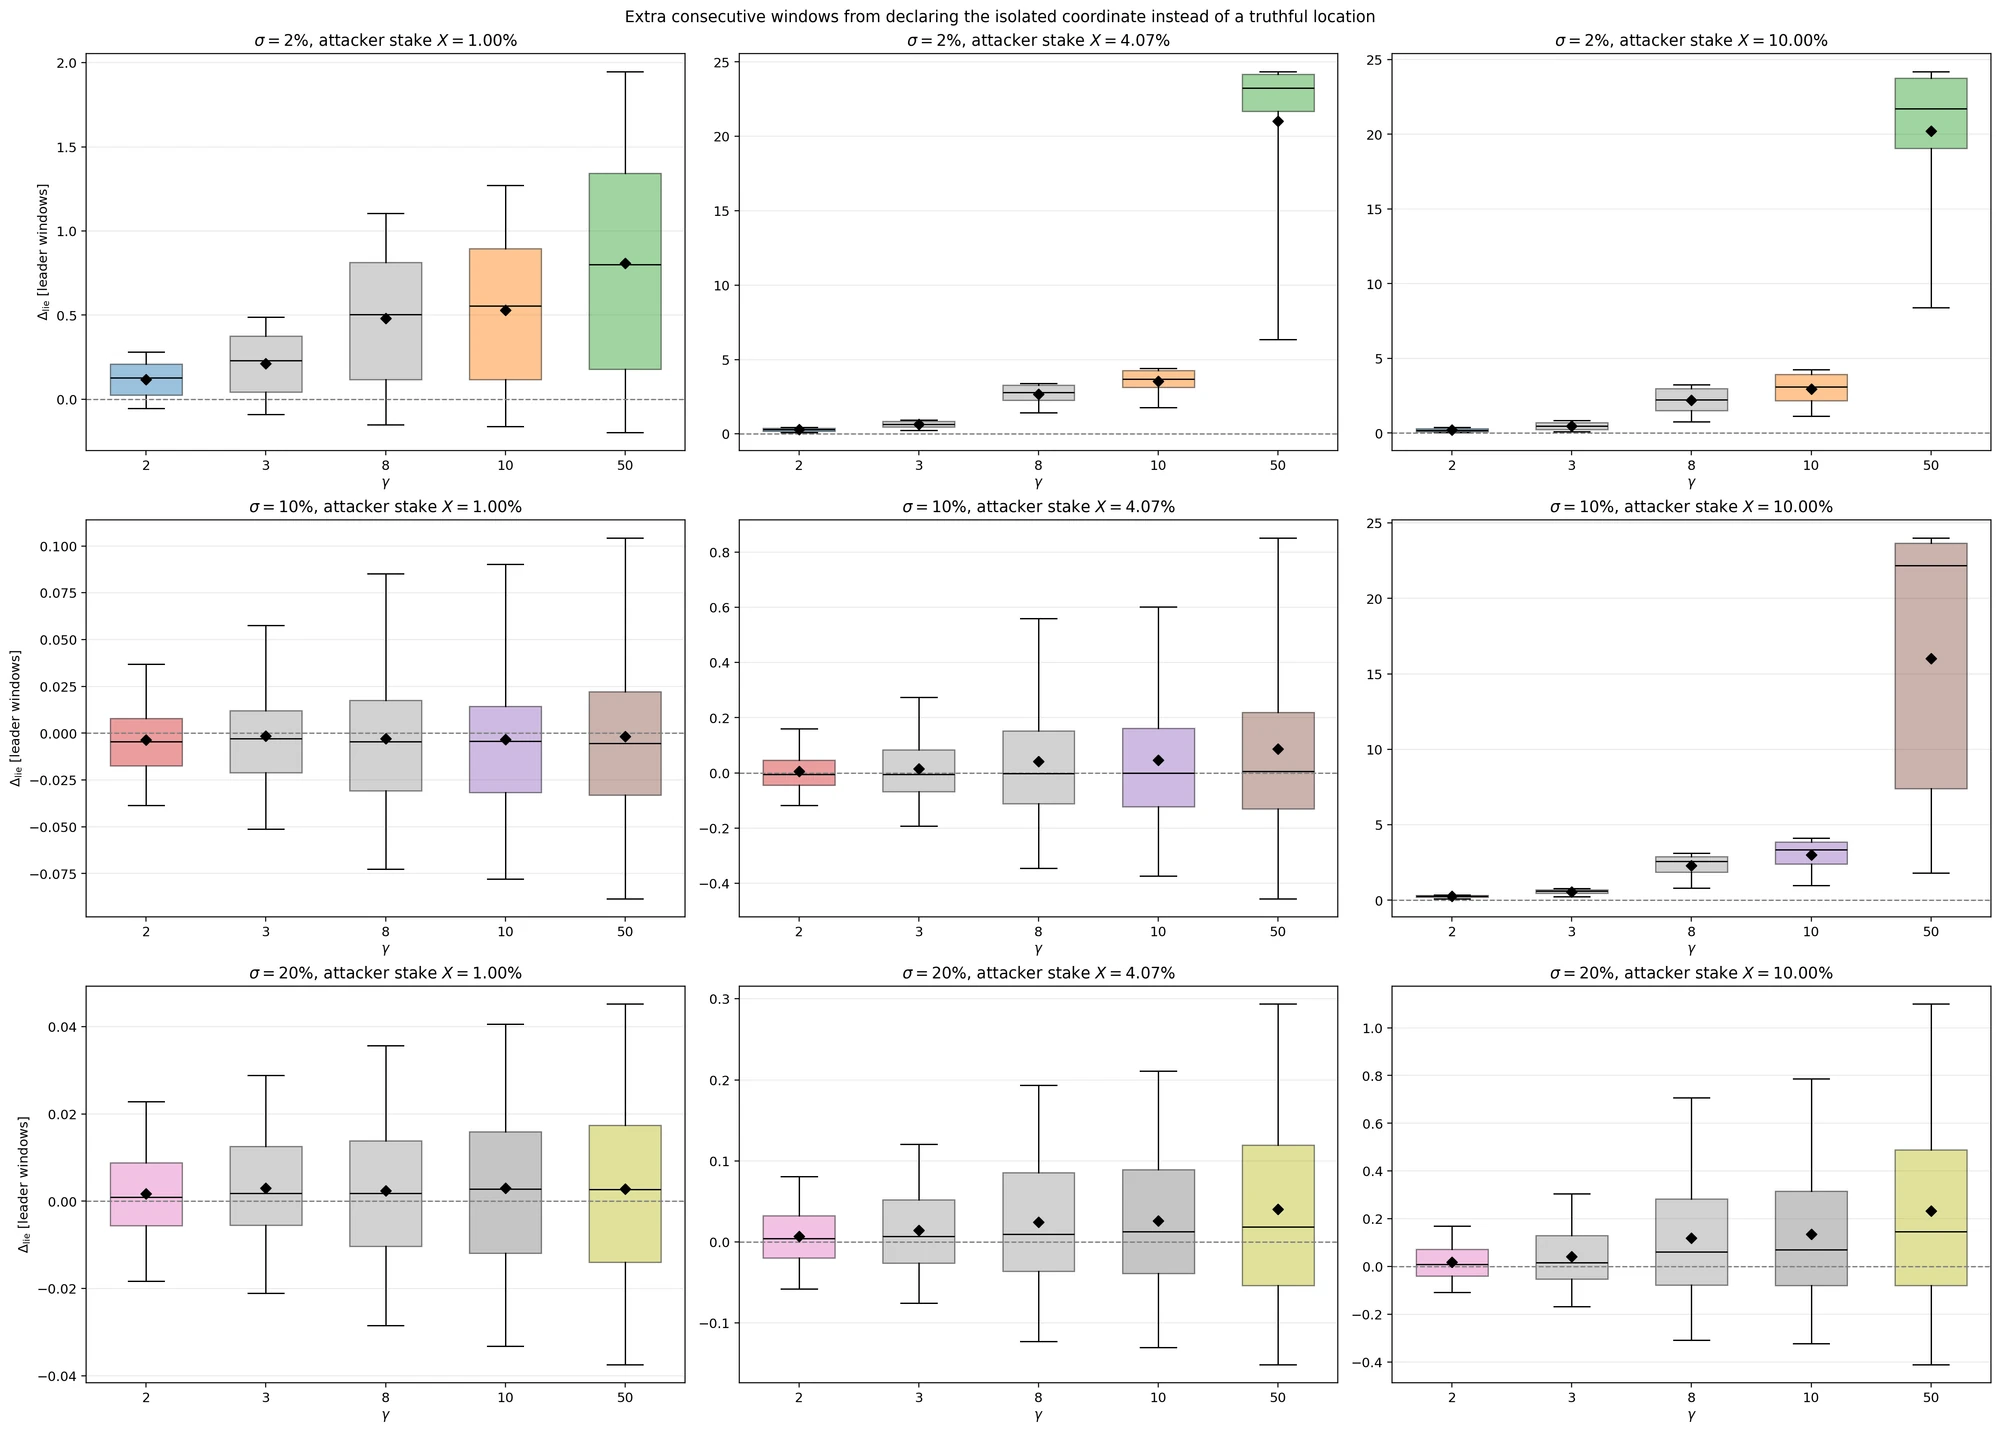
Fig. B4: Gain from lying about the location under the regional stake prior. Same layout as Fig. 8.
Spillover is still controlled by the ratio . Whenever a region holds less stake than , its bins fill with foreign leaders. Since this now happens to every region in about a third of the networks, the tails reach high shares everywhere. At and the 95th percentile of the external slot share is 0.86–0.88 in every region, against a mechanical maximum of 0.90.
What changes from one region to another is geography. At the same ratio , Asia's bins mix more than the others. When Asia holds between half and three quarters of , the median external share of its bins is 0.63, against 0.27–0.34 in the other regions. Asia's 14 datacenters are spread over thousands of kilometers, from Japan to India, and sit close to Europe and Oceania. Their radius reaches foreign stake before it has collected enough Asian stake. Europe suffers slightly, together with Oceania: their mean external share at and is 0.21, against 0.25 for Asia and 0.18–0.20 for the other regions.
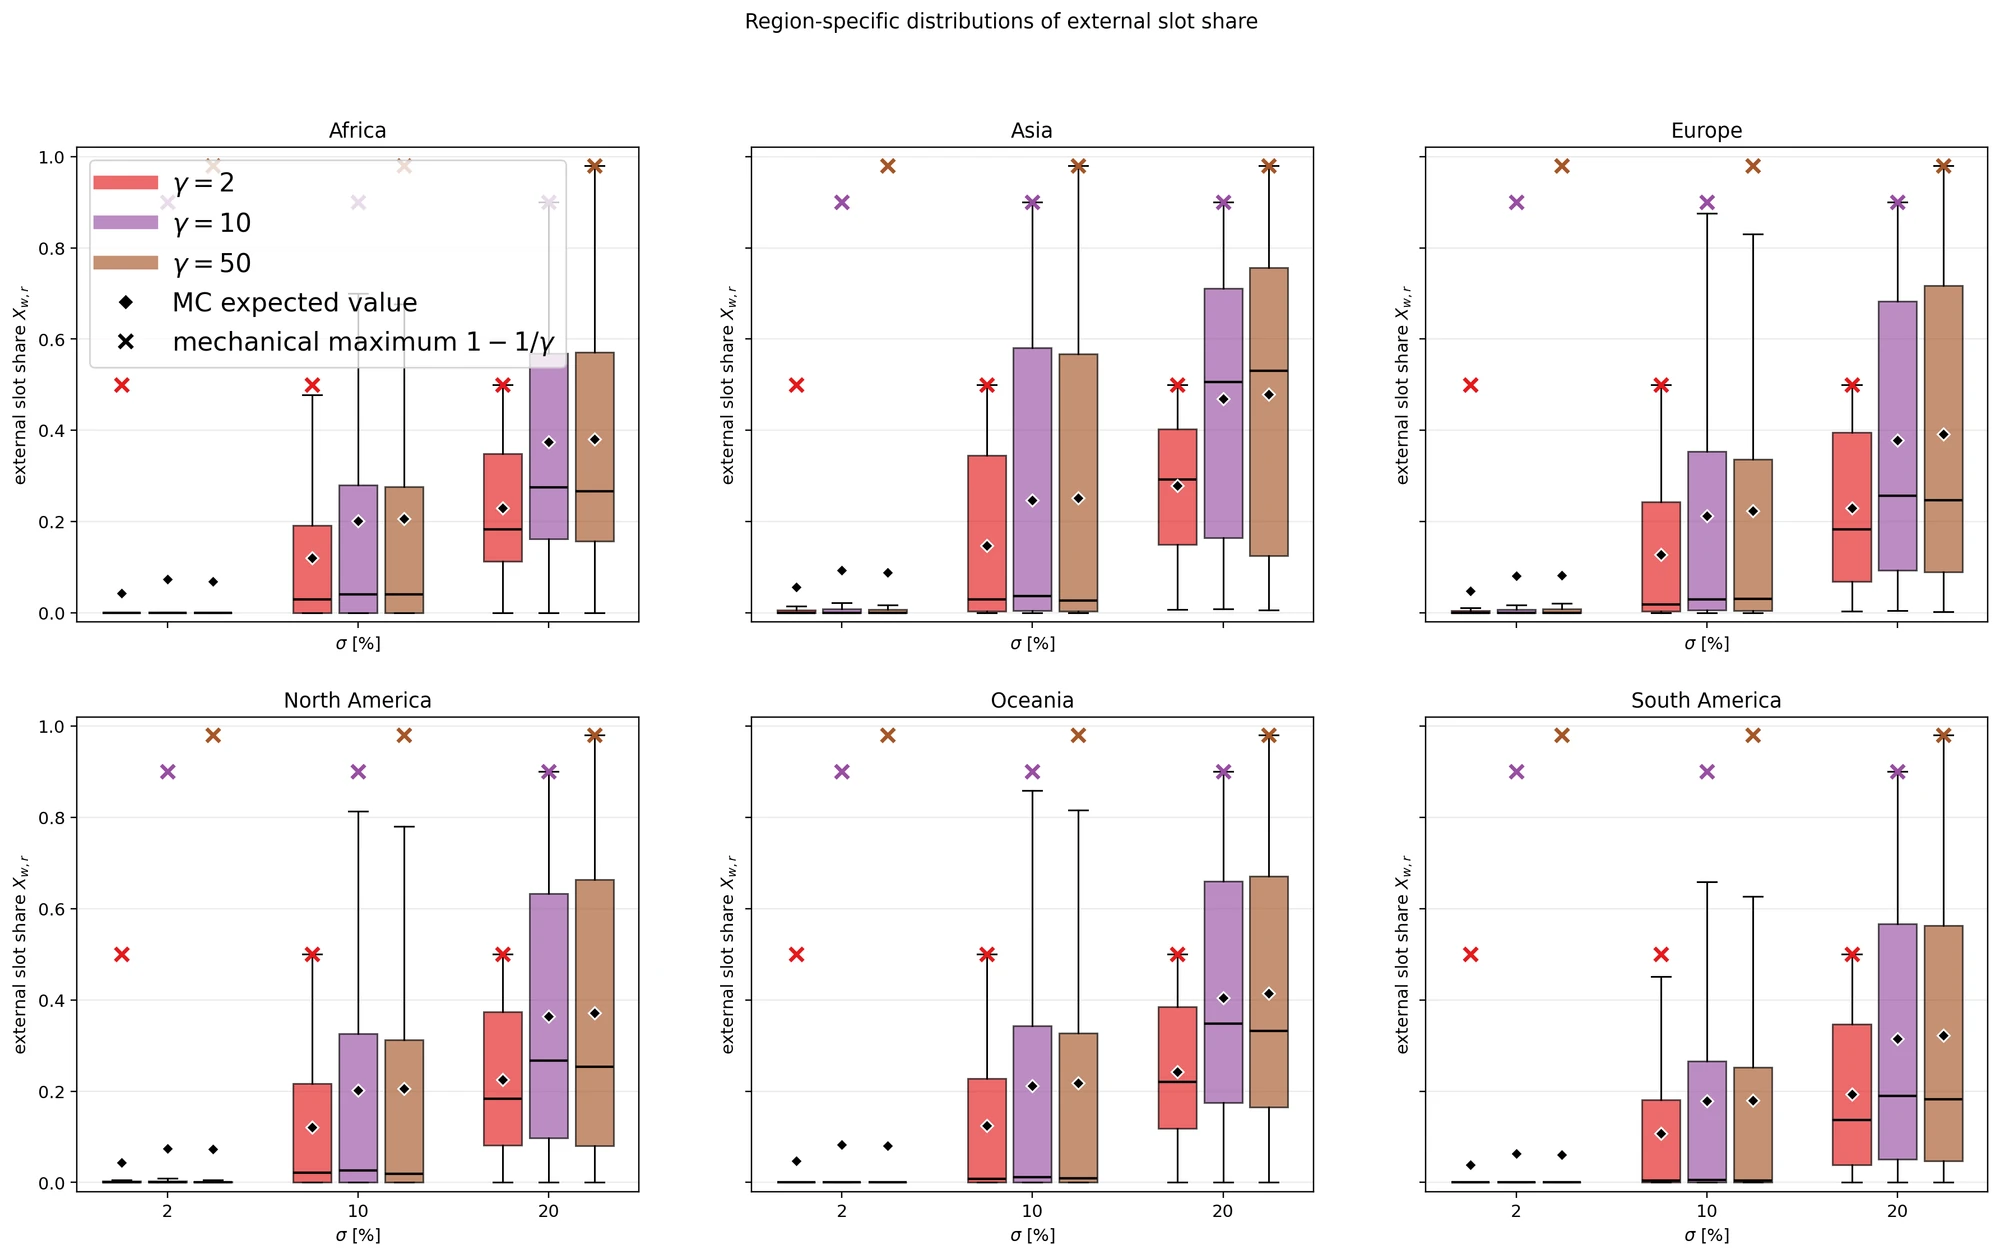
Fig. B5: External slot share by macroregion under the regional stake prior. Same layout as Fig. 7.
As in the main analysis, going beyond breaks the locality of the macroregions, starting from Asia.
With , the knees on regional metrics do not move. The knee of the handoff gain against stays at .
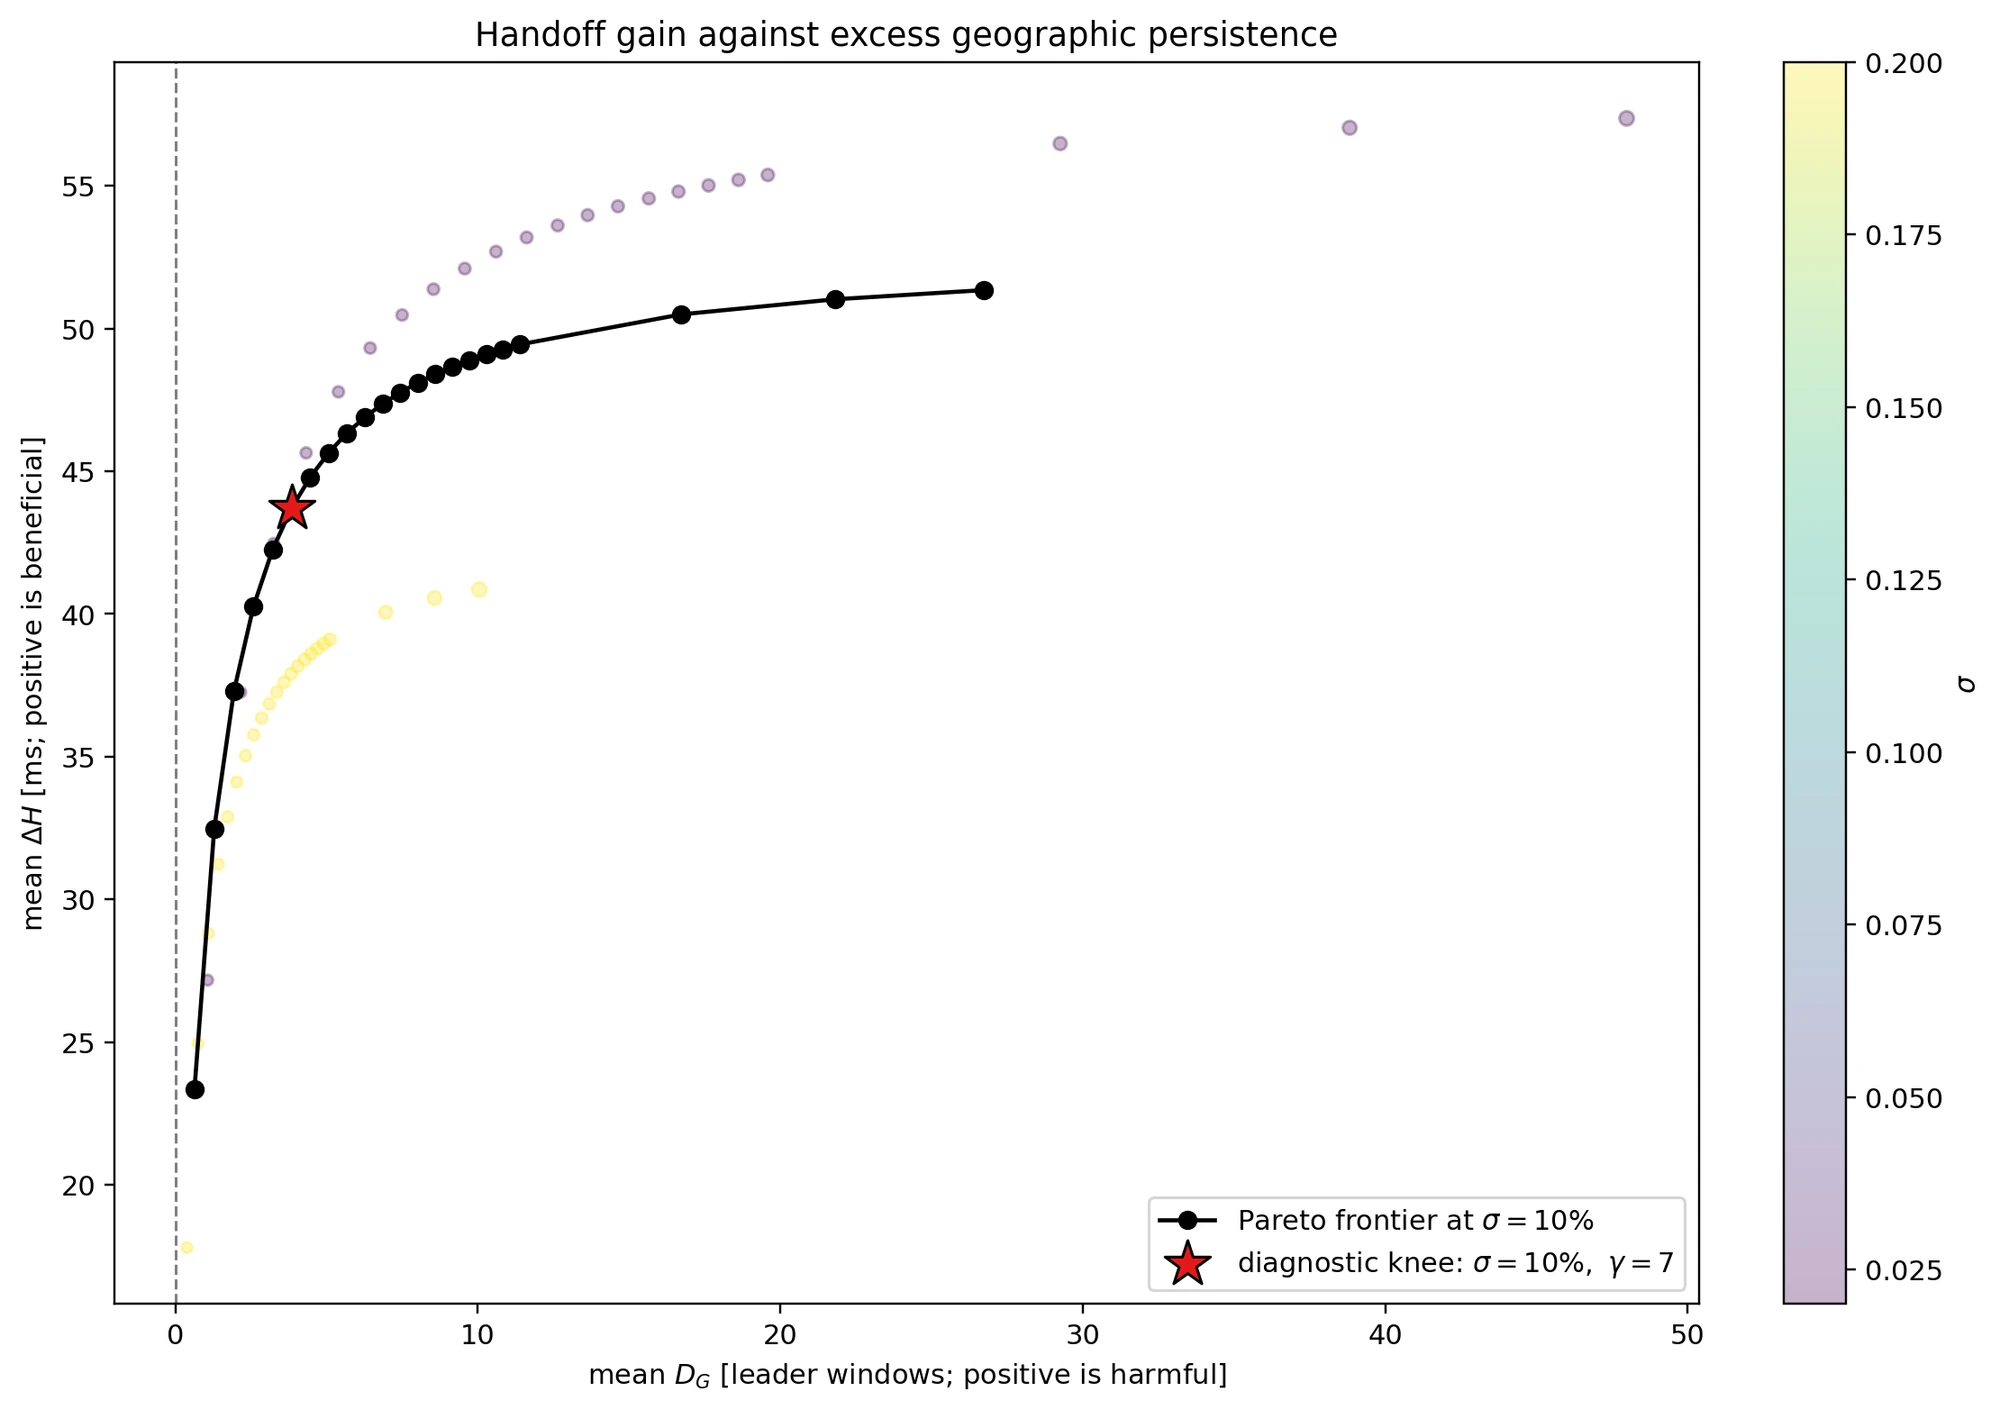
Fig. B6: Handoff gain against under the regional stake prior. Same layout as Fig. 9.
For the leader-level risks the picture is similar. With an attacker at , the knee is at for both and (7 and 6 in the main analysis). With an attacker below (), the knee against moves slightly up, from to , while the knee against stays at . In this case is tiny (0.03 windows at ), so the exact position of its knee carries little weight.
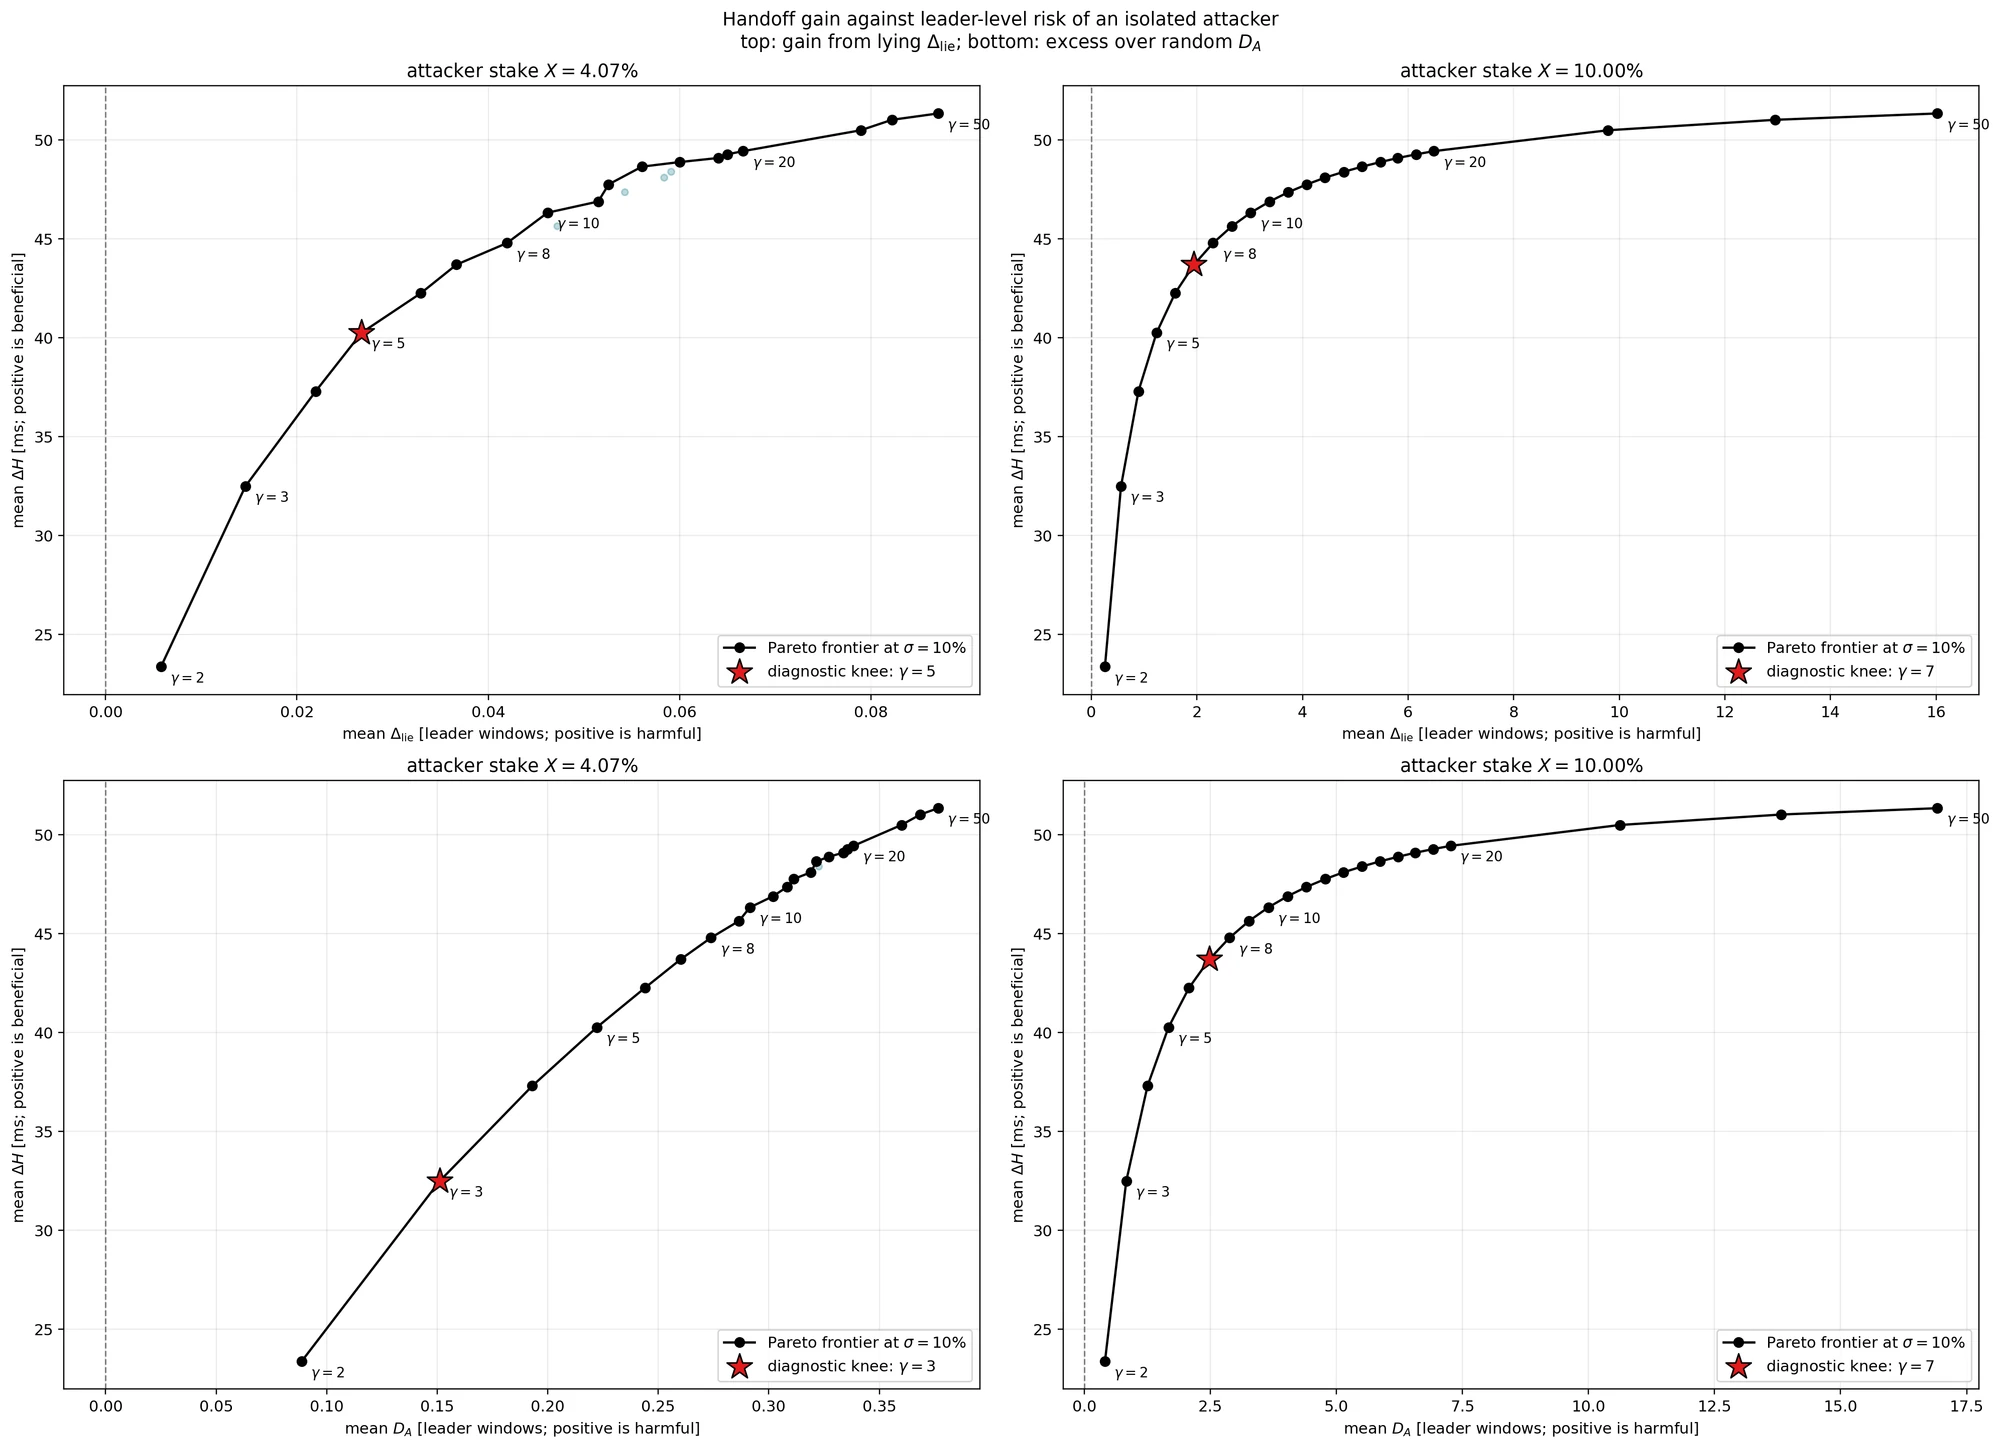
Fig. B7: Handoff gain against the leader-level risks, (top) and (bottom), for and , under the regional stake prior. Same layout as Fig. 10.
A more uniform and more mobile stake therefore preserves the main conclusions. Increasing is reduces the measured benefit from misreporting. Geography still caps around 10%, and at the choice of based on the knees is essentially unchanged.
Appendix C - Coalitions and Consecutive Slots
We can introduce the presence of coalitions and ask how the probability of obtaining consecutive windows changes when moving into geo-aware parameter space.
For coalitions here we refer to any type of collaboration between groups of validators. We use the same Gini-based simulation pipeline. Gini coefficients for coalition are in the set . This is because coalitions usually give incentives, and validators usually opt in into coalitions that pay the most.
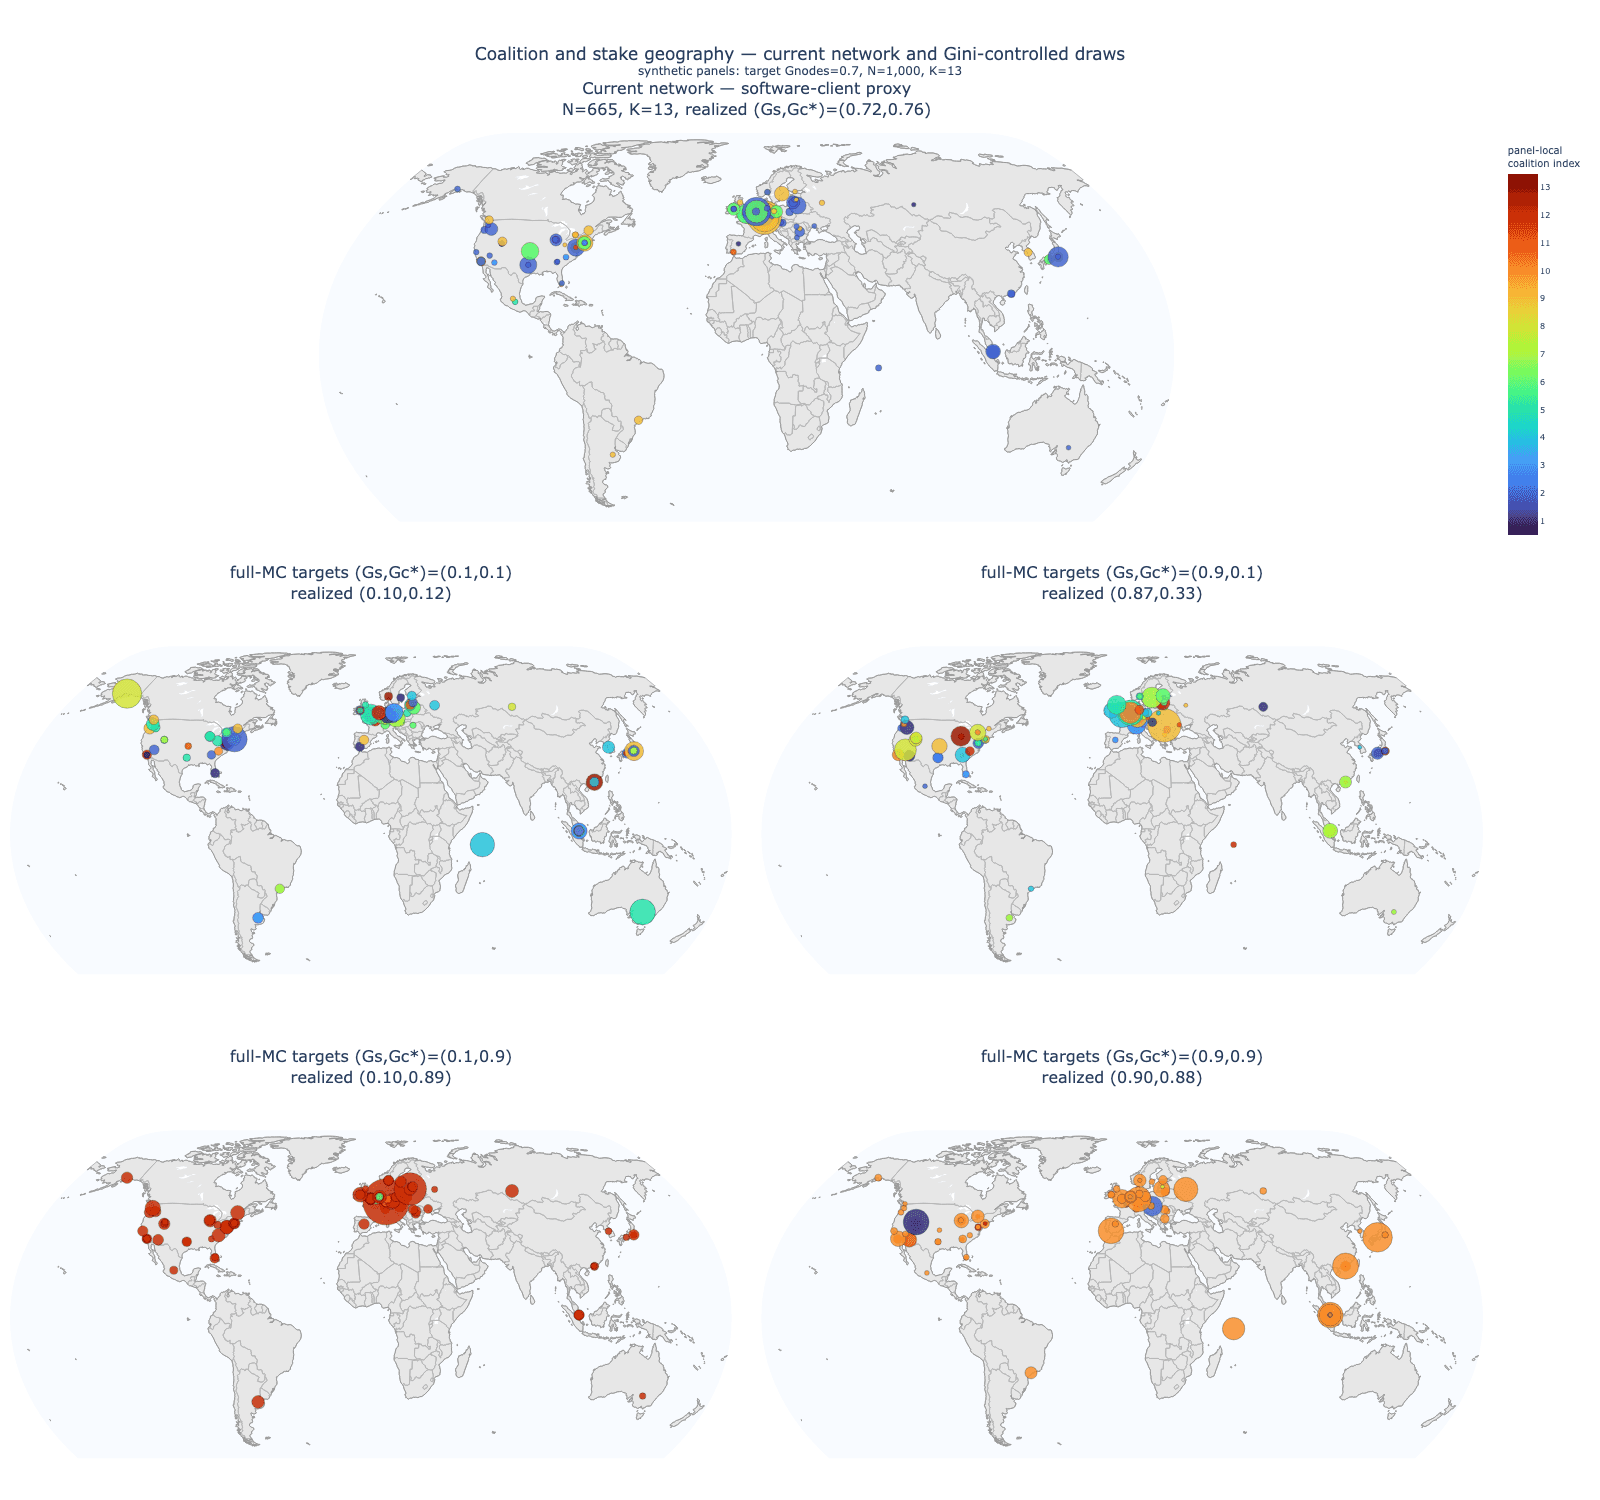
Fig. C1: Examples of regional coalitions distributions generated by the Gini prior.
At this point we can study the excess probability with respect to random of proposing consecutive windows.
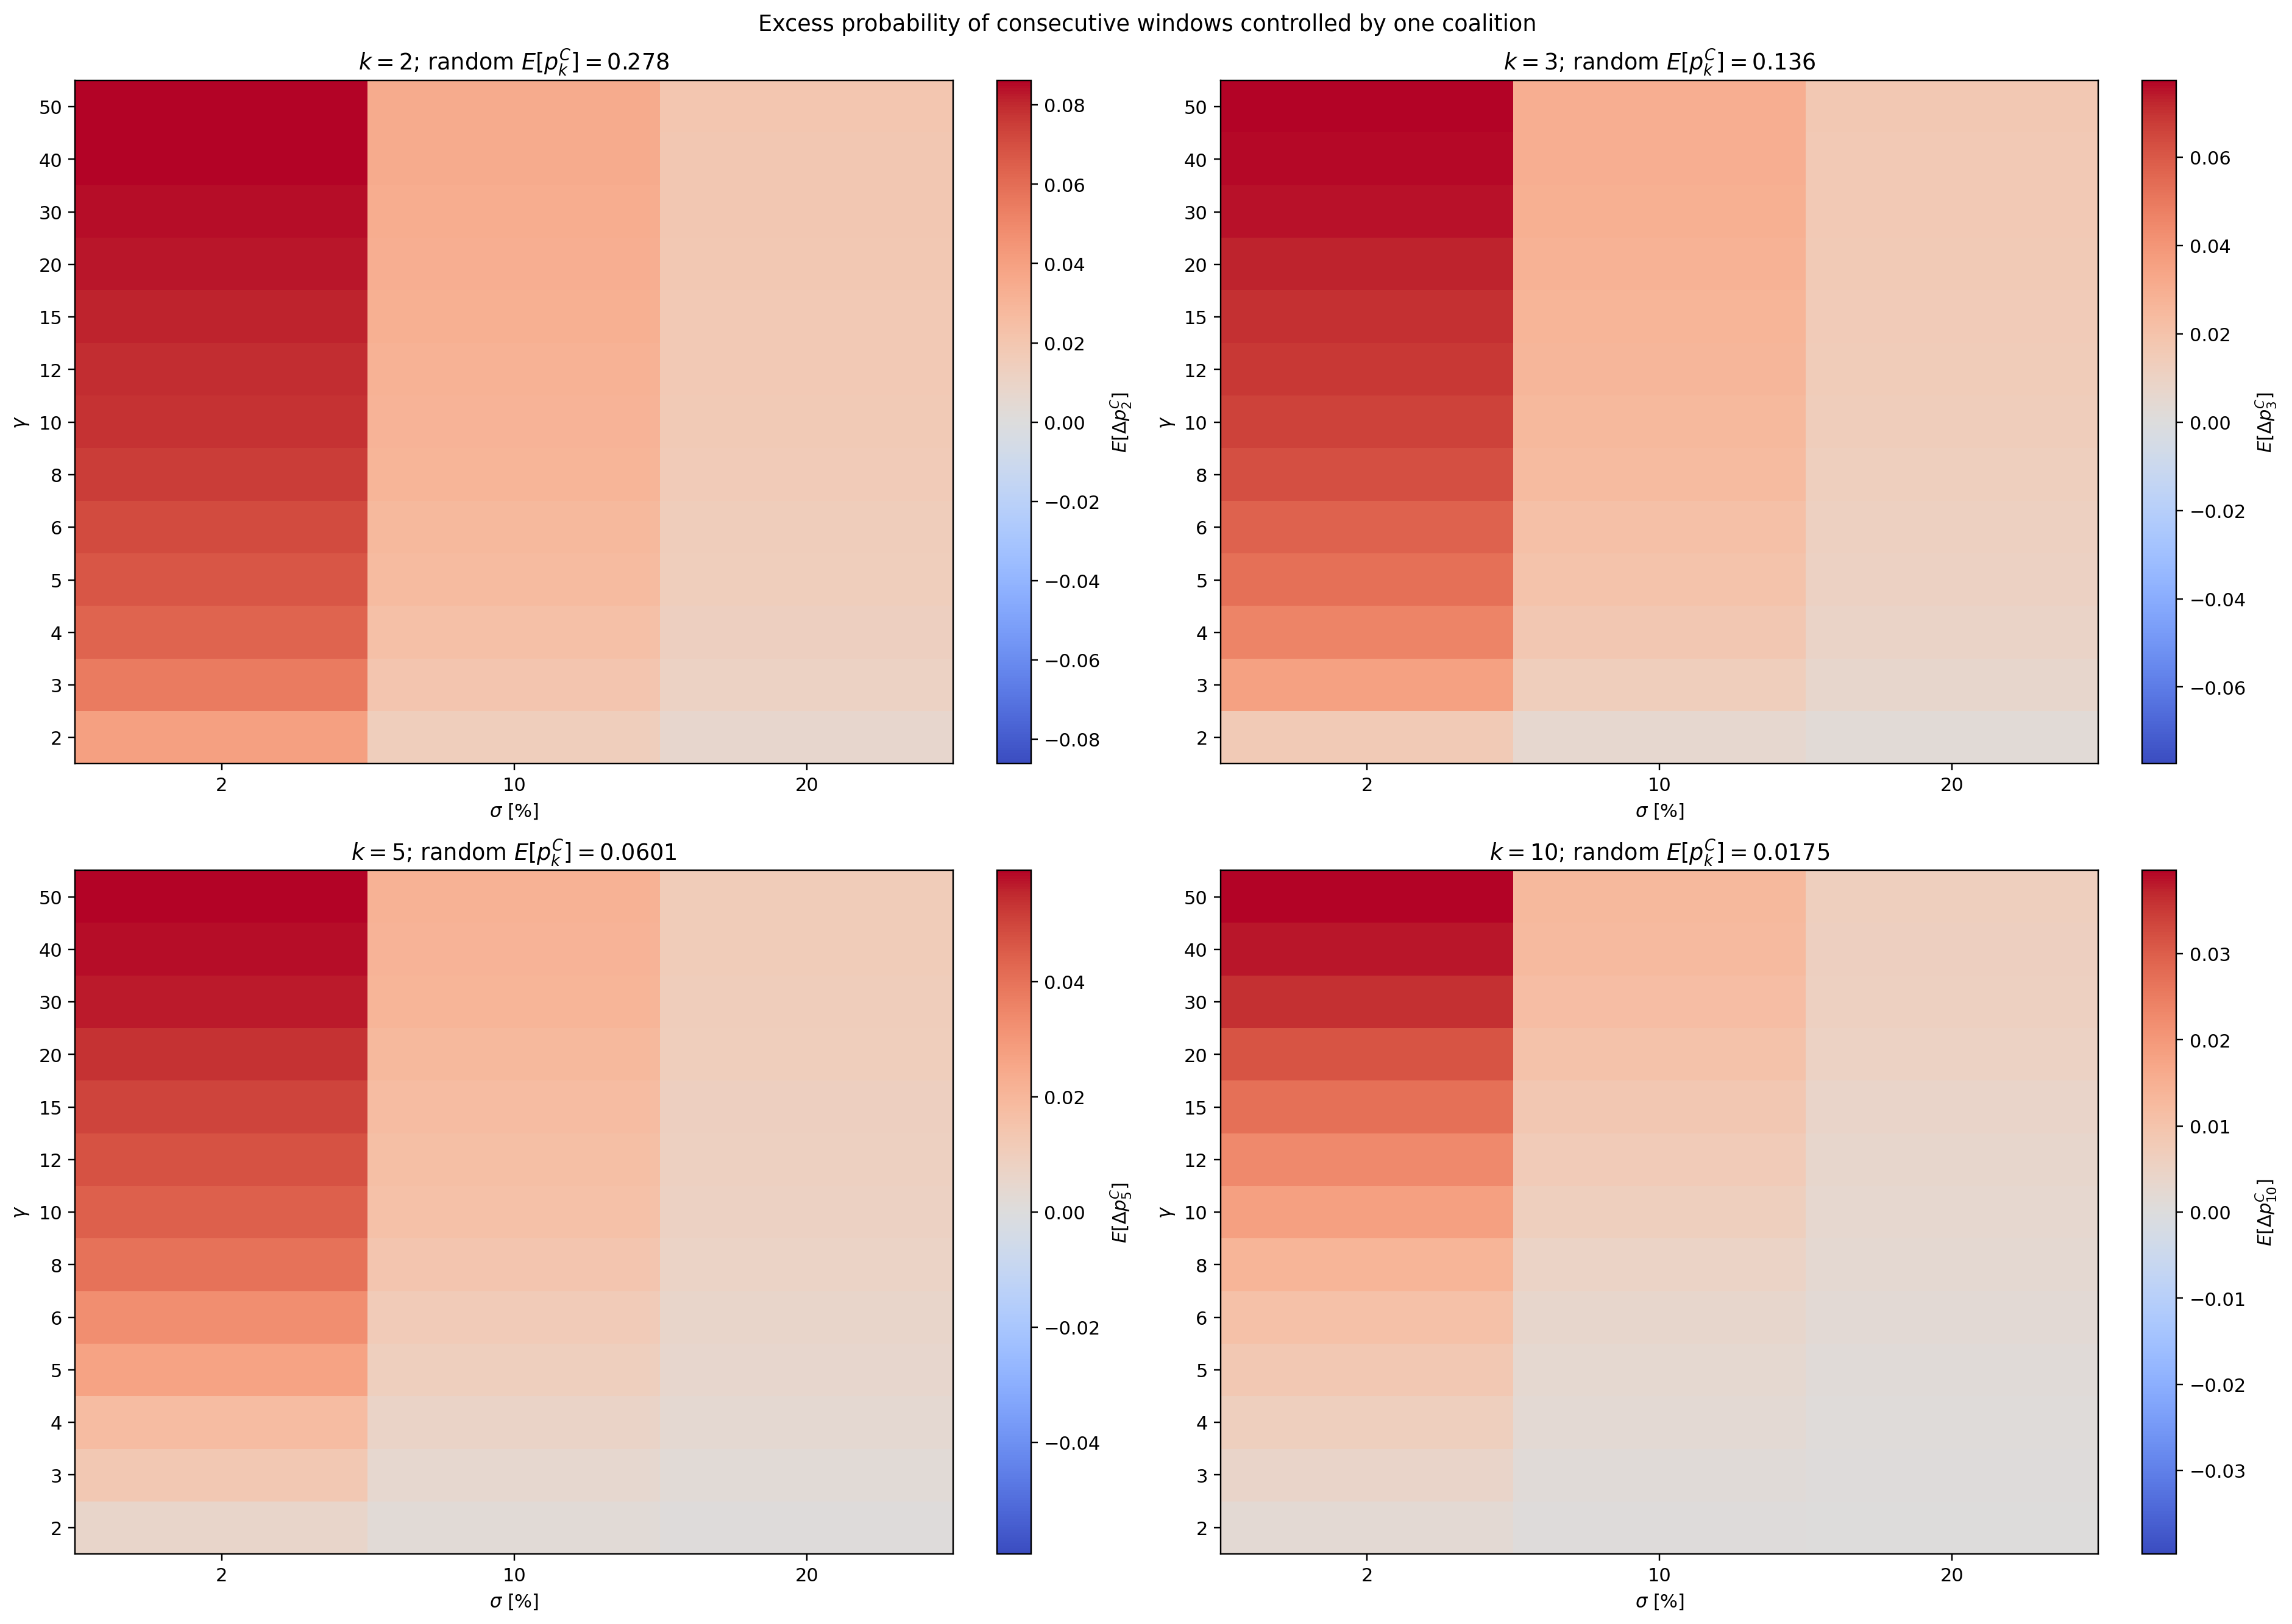
Fig. C2: Excess probability (with respect to random schedule) of obtaining 2, 3, 5, 10 consecutive windows.
Figure C2 shows how this probability changes. When fixing , we have
| leader windows | |||
|---|---|---|---|
| 2 | 29,83% | 30,72% (+0,89 pp) | 30,84% (+1,01 pp) |
| 3 | 14,85% | 15,93% (+1,08 pp) | 16,07% (+1,22 pp) |
| 5 | 6,46% | 7,43% (+0,97 pp) | 7,59% (+1,14 pp) |
| 10 | 1,86% | 2,23% (+0,37 pp) | 2,38% (+0,52 pp) |
We observe that the absolute increments remain limited in the configurations considered. At , the probability that three consecutive leader windows belong to the same coalition moves from approximately 14.85% at to 16.07% at . For 10 consecutive windows, it moves from 1.86% to 2.38%: a relative increase of approximately 28%, but an absolute increase of 0.52 percentage points.
This is relevant when assessing additional opportunities for coalition-based MEV. The radius schedule preserves each coalition’s total number of leader windows but changes their temporal arrangement. In these simulations, increasing produces a limited absolute increase in consecutive coalition control. However, this does not directly quantify additional MEV revenue.
Appendix D - Sensitivity to incorrect geographical coordinates
Incorrect coordinates can arise from deliberate misreporting or operational changes, such as relocating a validator without updating its declared position. We assess this mismatch using a synthetic validator holding stake fraction . Scheduling uses declared coordinates, while outcomes are evaluated at physical locations.
For each metric, reference schedule and parameter configuration, we select a declared coordinate that maximizes the frequency of deterioration on training networks, then evaluate it on separate validation networks. Figure D1 reports
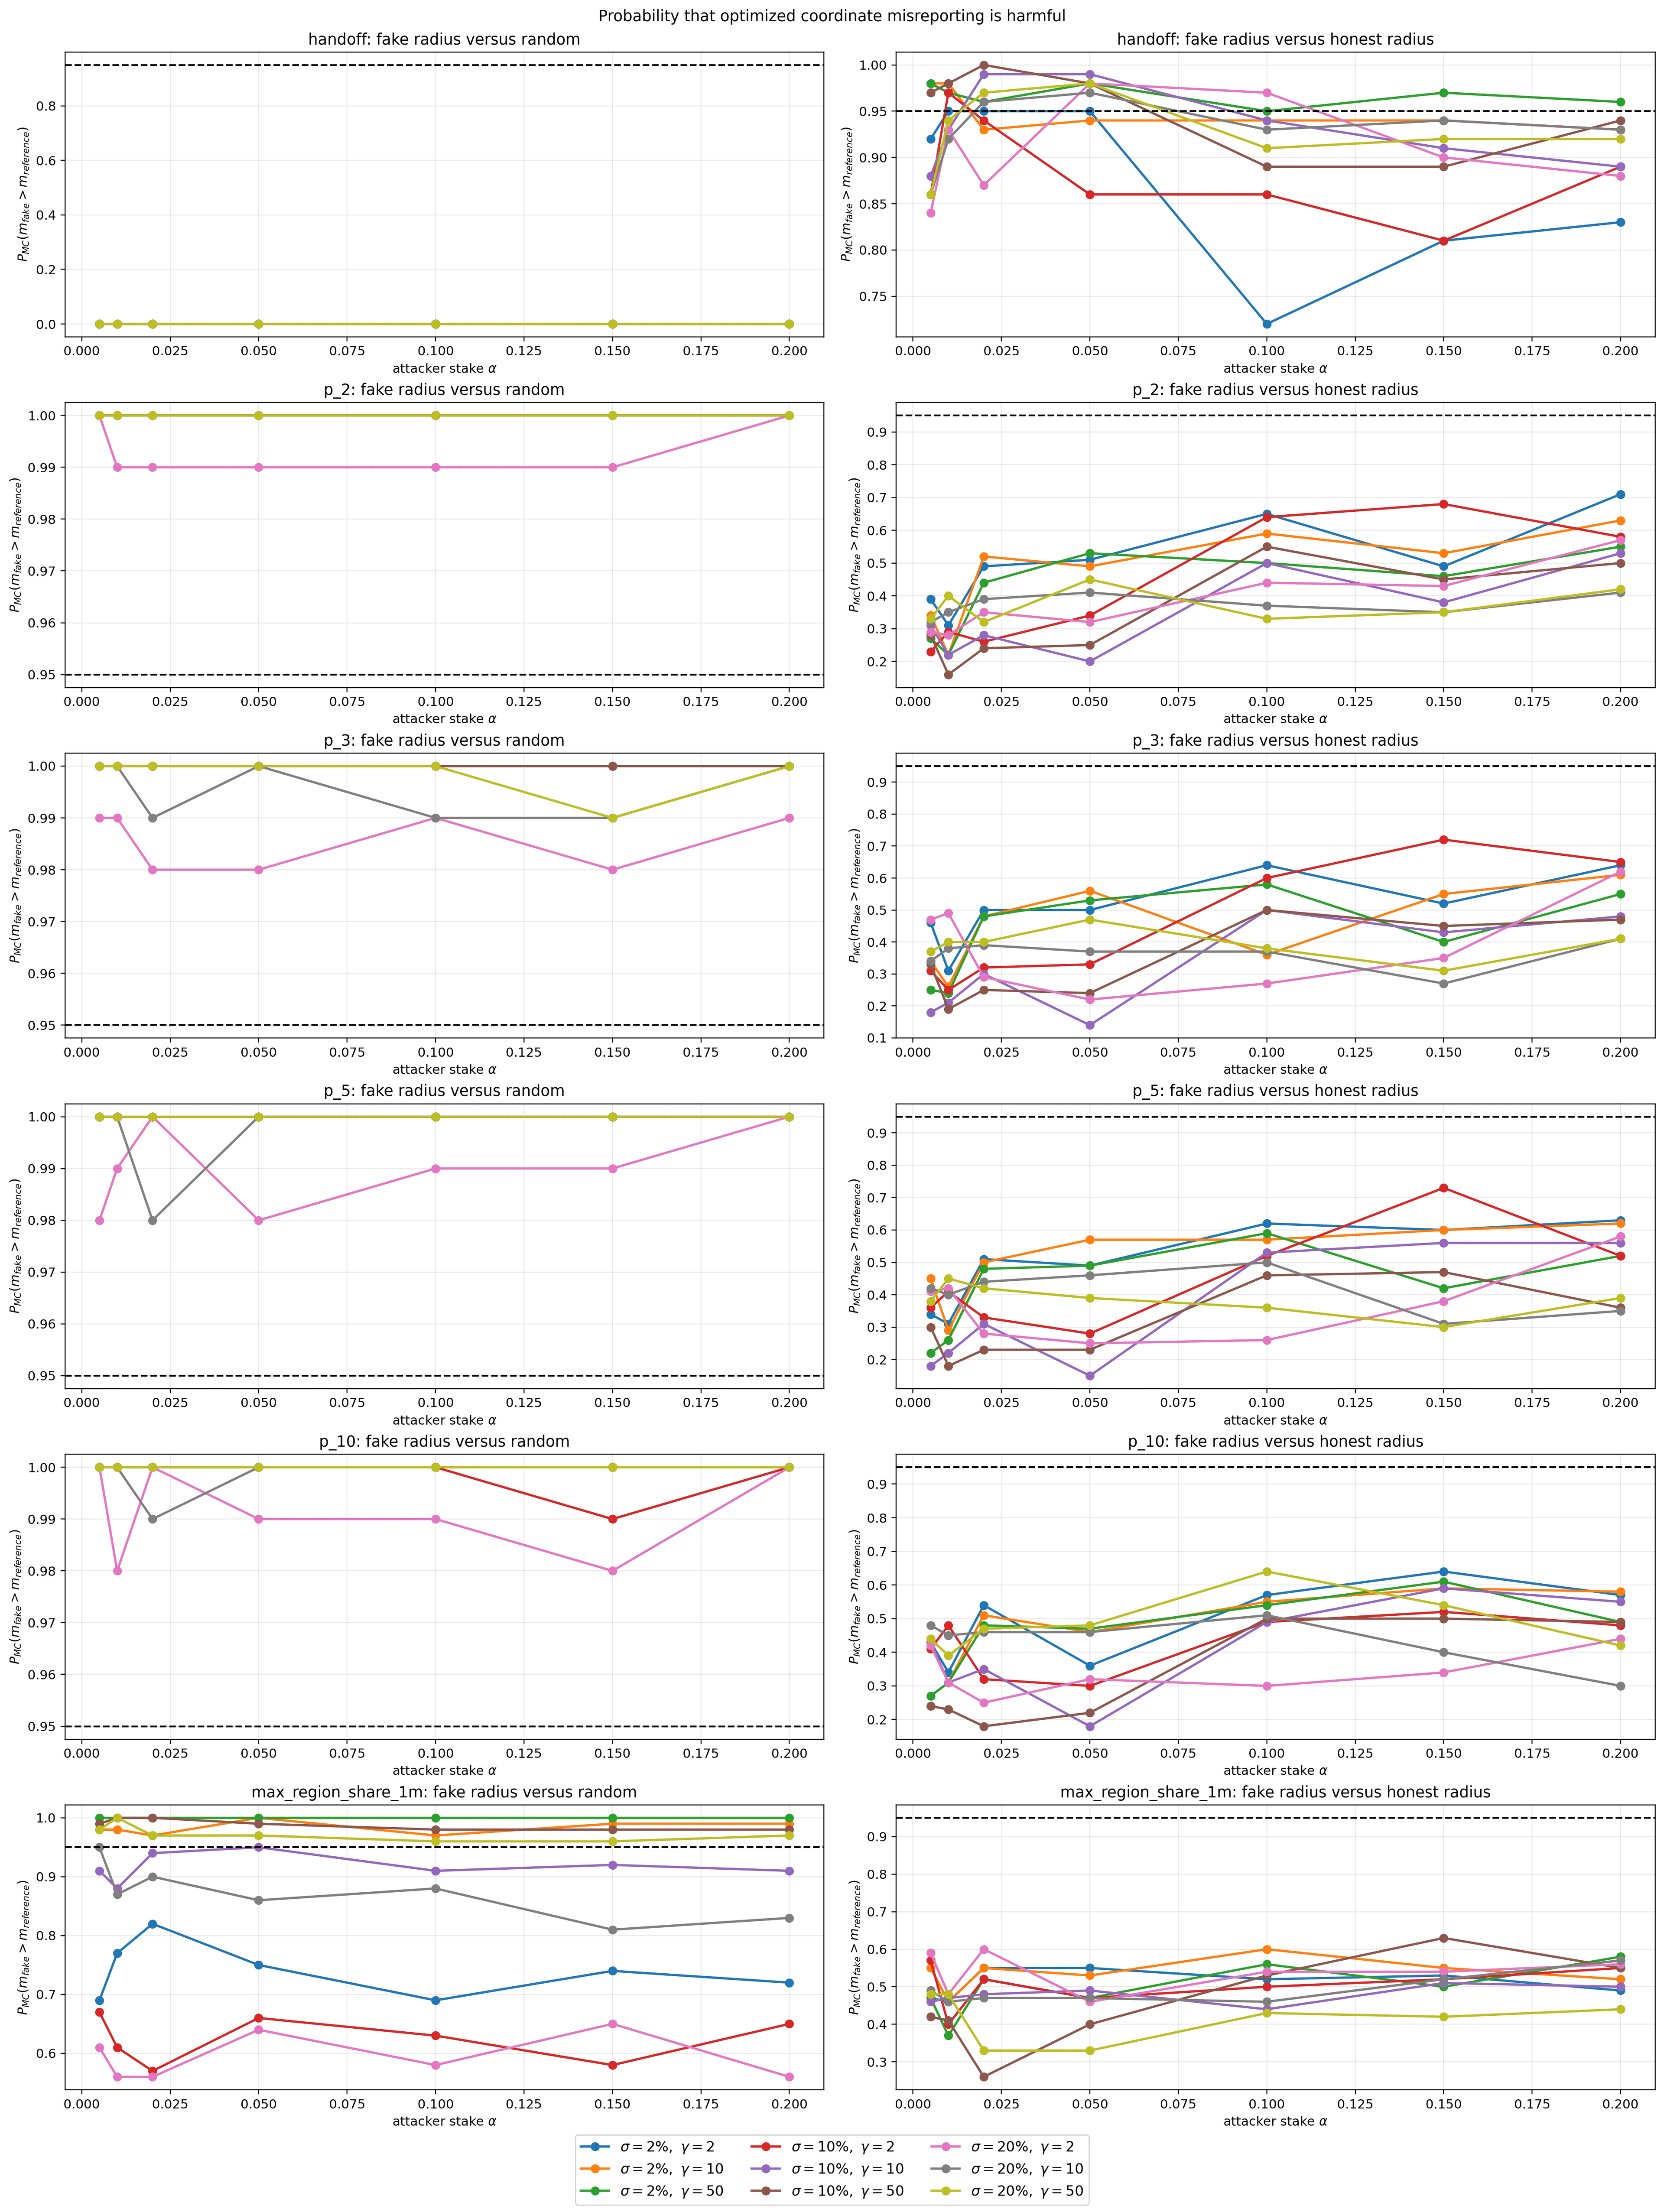
Fig. D1: Sensitivity to optimized coordinate misreporting. Each curve shows the fraction of validation networks in which incorrect coordinates increase the metric indicated by the row, relative to random scheduling (left) or correctly reported radius scheduling (right). The horizontal axis gives the stake fraction assigned to the misreporting validator; colors identify . Rows report mean handoff latency, same-macroregion persistence for consecutive leader windows, and mean maximum regional occupancy over one-minute intervals. Declared coordinates are selected separately for each metric, reference and parameter configuration on training networks, then held fixed during validation. All outcomes use physical locations. The dashed line marks a 95% frequency of deterioration, not a confidence interval. Probabilities describe the frequency, not the magnitude, of deterioration.
Columns compare against random scheduling and correctly reported radius scheduling. The dashed line marks 95%, not a confidence interval.
Misreporting frequently increases mean handoff relative to correctly reported radius scheduling. Nevertheless, no handoff deterioration relative to random is observed in the displayed validation results, even at .
Geographic persistence is almost always higher than under random scheduling. However, its additional deterioration relative to correctly reported radius scheduling is less consistent. The same distinction applies to mean maximum regional occupancy over one-minute intervals. Thus, comparison with random includes the clustering already introduced by the radius algorithm; it does not isolate the effect of incorrect coordinates.
These curves measure how often deterioration occurs, not its magnitude. They describe an adversarially selected coordinate-mismatch stress test, rather than the expected impact of routine relocations.